Router-R1 精读NeurIPS 2025 · arXiv 2506.09033
阅读笔记 · 2026-10-31 · 多模态 agent 项目的基座论文

Router-R1:用强化学习教一个 3B 小模型做多轮 LLM 路由与聚合

Zhang, Feng, You(UIUC),NeurIPS 2025。把"该问哪个 LLM"变成一个序贯决策:policy LLM 在一条生成轨迹里交替 <think>、<search>LLM-Name: query</search>、<information>,最后给出 <answer>;reward = 格式 + 答对 + 成本。本页把论文的算法和官方代码放在一起读:左边是论文怎么说,右边是代码怎么做;第三个 tab 是为我们的多模态项目做的 52 个 VQA 数据集调研。

arXiv 2506.09033 (v3, 2025-10-24)github ulab-uiuc/Router-R1HF 权重与数据base: Qwen2.5-3B-Instruct / Llama-3.2-3B-Instruct · PPO (veRL) · 7 个 QA 数据集

一页看懂

问题现有 LLM router 做的是"一次性把 query 分给一个模型"。复杂问题需要多个模型多轮配合,而"选哪个模型"是离散、不可微的决策。
做法把路由写成序贯决策:一个 3B 的 policy LLM 在生成里交替 think / route / 吸收返回信息,最多 4 轮路由,最后自己写答案。用 PPO(veRL)训练,被调模型的回复不进 loss。
Reward三项规则奖励:格式(−1 / 0)、结果(Exact Match)、成本(被调模型的输出 token × 单价,滑动窗口归一化后取反)。r = Rformat + (1−α)Routcome + αRcost,分层生效。
结果只用 NQ + HotpotQA 各 7K 训练,7 个 QA 数据集平均 EM 0.416(Qwen base)/ 0.409(Llama base),比最强 baseline Largest LLM 高 0.078 / 0.059;α 调到 0.9 成本降 27 倍。
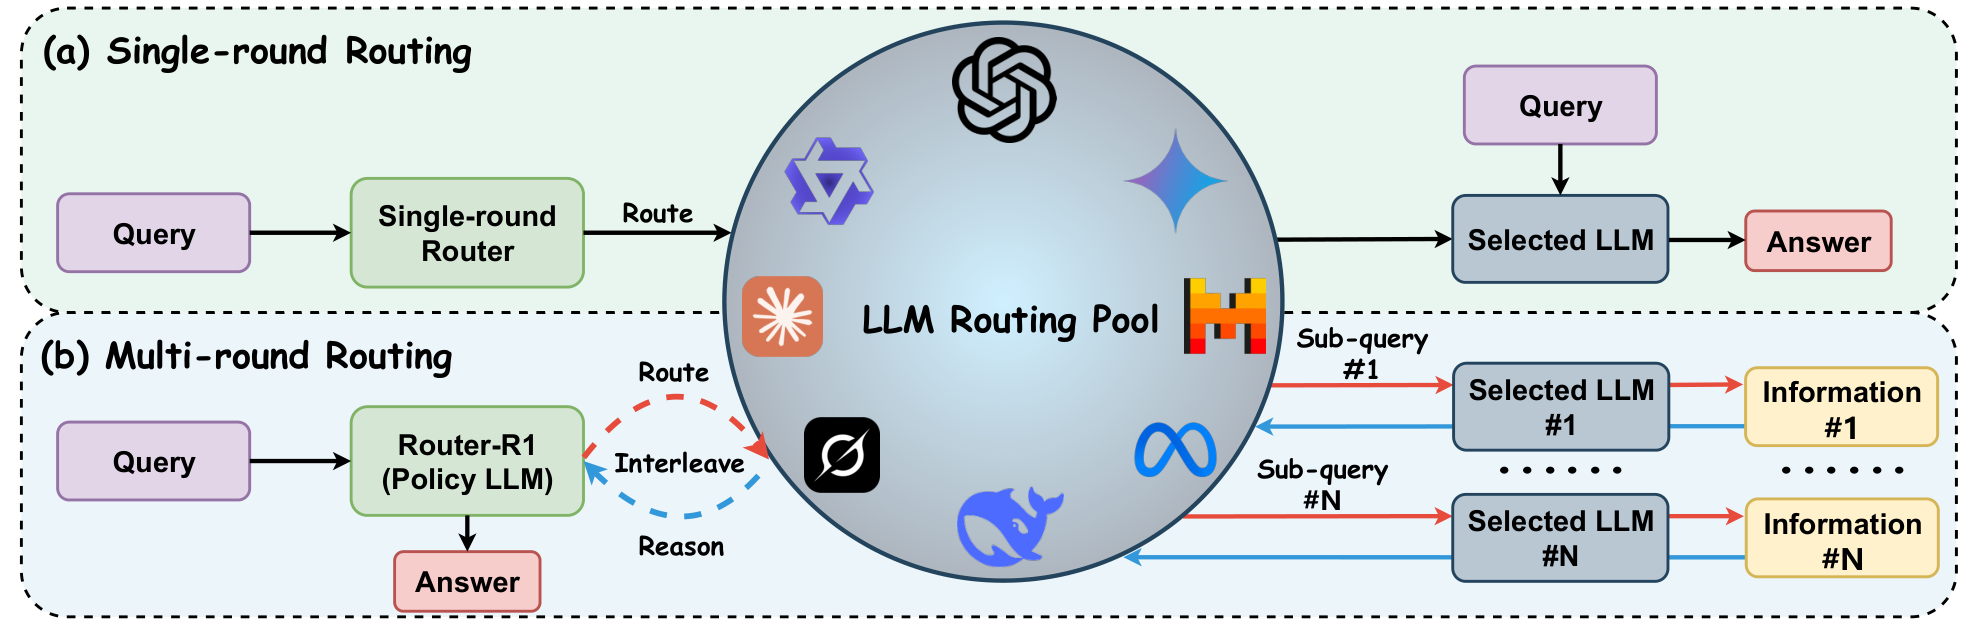
Router-R1 overview: single-round routing versus multi-round routing with a policy LLM interleaving reasoning and routing
Figure 1(论文). 上:单轮路由,query → router → 某一个 LLM → 答案。下:Router-R1,policy LLM 自己推理、把子问题发给池子里不同的 LLM、把返回的信息拼回上下文再推理,最终答案由 policy LLM 产出。图中的商业模型 logo 只是示意,实验用的池子是 6 个开源模型(通过 NVIDIA NIM API)。

问题设定与形式化

论文把 LLM router 的现状概括为 single-round, one-to-one mapping:每个 query 独立地交给一个模型。它指出两个困难:第一,每一轮"调用哪个 LLM"是离散选择,梯度方法(RouterDC、GraphRouter、FrugalGPT、HybridLLM 这类单次 router)扩展到多轮会迅速不可行,所以用 RL;第二,多跳问题需要"推理 ↔ 选模型"交错进行,而不是选一次、拿结果、结束。

于是 router 本身被实例化为一个 LLM(policy)。它的一条生成轨迹 y 里穿插了池子 𝒫 中模型的回复,优化目标是带 KL 正则的期望奖励(论文 Eq. 1):

Eq. (1)maxπ 𝔼x∼D, y∼π(·|x; 𝒫) [ rφ(x, y) − β · log π(y|x; 𝒫) / πref(y|x; 𝒫) ]

这是通用形式(论文说可以套 PPO / GRPO);实际用 veRL 的 PPO + GAE,β 在代码里是 algorithm.kl_ctrl.kl_coef=0.001,KL 作为 token 级惩罚加在 reward 上。动作空间完全由四种 tag 定义:

tag谁写含义代码里的处理
<think>…</think>policy内部推理。prompt 要求每次收到新信息都先 think,并说明"为什么需要外部信息、选哪个模型"。不解析内容;格式奖励要求整段回复以 <think> 开头、至少一个且内容非空。
<search>LLM-Name: query</search>policy路由动作:选一个候选模型,并给它一个具体子问题。论文正文把它写成 <route>,代码沿用 Search-R1 的 <search>。postprocess_predictions 用正则取第一个 tag,按冒号切成模型名和子问题;名字经 check_llm_name 子串匹配映射到 API id。
<information>…</information>环境被调模型的回复(论文写作 <info>),拼回上下文。截断到 600 token;这些 token 在 PPO loss 里被 mask 掉(state masking)。
<answer>…</answer>policy最终答案,结束 episode。extract_solution 取最后一个 answer 块,归一化后做 EM / F1。
每轮只允许一个动作:_postprocess_responses 在第一个 </search>(否则第一个 </answer>)处截断,re.search 只取第一个 tag。"并行子问题 A、B"在这套协议里不存在,要做我们的 evidence graph 必须扩展解析器和环境步。

动作协议与 prompt

整个"动作空间"就是 prompt 里的几条规则加 6 段模型描述(descriptor)。descriptor 是让 GPT-4o 读 NVIDIA 的 model card 写成的能力简介,论文称其只是 cold-start prior:训练中 policy 通过交互和 reward 自己学到各模型的真实强弱;新模型只要把描述追加进 prompt 就能零重训接入。

paper · 2_Method.tex Figure 2

训练 prompt 模板要求:每次收到新信息先在 <think> 里推理;缺知识就写 <search>Candidate LLM: Query</search>;每次调用前必须说明"为什么需要外部信息"和"哪个 LLM 最合适";不要只盯着一个模型反复调,鼓励探索不同模型、也允许对同一问题多次调用。

注意:论文的 Intro 与 Limitations 说 descriptor 包含 pricing, latency, example performance,但附录给出的 descriptor 原文和代码里的字符串都只有规模、语言和特长,没有价格和延迟。成本信号完全来自 reward。

data_process/prompt_pool.pyL2–L9
2Answer the given question. \
3Every time you receive new information, you must first conduct reasoning inside <think> ... </think>. \
4After reasoning, if you find you lack some knowledge, you can call a specialized LLM by writing a query inside <search> LLM-Name:Your-Query </search>. \
5
6!!! STRICT FORMAT RULES for <search>: !!!
7    + You MUST replace LLM-Name with the EXACT name of a model selected from [Qwen2.5-7B-Instruct, LLaMA-3.1-8B-Instruct, LLaMA-3.1-70B-Instruct, Mistral-7B-Instruct, Mixtral-8x22B-Instruct, Gemma-2-27B-Instruct]. \
8    + You MUST replace Your-Query with a CONCRETE QUESTION that helps answer the original question below. \
9    + NEVER copy or paste model descriptions into <search>.
router 的 prompt 开头:规则 + 候选名单。行尾的反斜杠是 Python 续行符,渲染后好几条规则会粘在同一行;复现时必须用完全相同的字符串,否则和训练 parquet 里的 prompt 不一致。
descriptor 示例

每个候选一段,共 6 段(Qwen2.5-7B、LLaMA-3.1-8B/70B、Mistral-7B、Mixtral-8x22B、Gemma-2-27B)。附录 Table 6 把它们压缩成一句话后平均 EM 从 0.416 变成 0.419:descriptor 的丰富度几乎不影响结果。

data_process/prompt_pool.pyL24–L28
24Qwen2.5-7B-Instruct:\
25Qwen2.5-7B-Instruct is a powerful Chinese-English instruction-tuned large language model designed for tasks in language, \
26coding, mathematics, and reasoning. As part of the Qwen2.5 series, it features enhanced knowledge, stronger coding and \
27math abilities, improved instruction following, better handling of long and structured texts, and supports up to 128K \
28context tokens. It also offers multilingual capabilities across over 29 languages.\
Qwen2.5-7B-Instruct 的 descriptor。文本硬编码在 prompt 里,论文里的 {candidates_intro} 只是概念上的占位。
给被调模型的 prompt · Appendix C

池子里的模型只收到子问题,看不到原问题、历史或图像。prompt 要求它尽力回答或给背景,回答控制在 512 token 内,并且完全答不了时必须明说并让 base model 去问别的 LLM——附录案例里"先问 8B、失败再升级到 70B"的级联行为,升级信号正是从这句话来的。

router_r1/llm_agent/route_service.pyL91–L107
91AGENT_PROMPT = """
92You are a helpful assistant. \
93You are participating in a multi-agent reasoning process, where a base model delegates sub-questions to specialized models like you. \
94\nYour task is to do your **absolute best** to either: \n
95    + Answer the question directly, if possible, and provide a brief explanation; or \n
96    + Offer helpful and relevant context, background knowledge, or insights related to the question, even if you cannot fully answer it. \
97
98If you are completely unable to answer the question or provide any relevant or helpful information, you must: \n
99    + Clearly state that you are unable to assist with this question, and \n
100    + Explicitly instruct the base model to consult other LLMs for further assistance. \
101
102**Important Constraints**: \n
103    + Keep your response clear, concise, and informative (preferably under 512 tokens). Your response will help guide the base model’s reasoning and next steps. \n
104    + Stay strictly on-topic. Do not include irrelevant or generic content. \
105
106\n\nHere is the sub-question for you to assist with: {query}\n
107"""
AGENT_PROMPT:被调 LLM 看到的全部内容。代码写的是 "multi-agent reasoning process",论文附录是 "multi-round"。

多轮交互循环

question x+ prompt + descriptors policy LLM (3B)Qwen2.5-3B / Llama-3.2-3B <think> 为何需要外部信息、选谁 <search>LLM-Name: q</search> <information>…≤600 tok <answer> … </answer> 每轮一个动作;上下文 ≤4096 token,左截 routing pool 𝒫OpenAI-compatible API, ThreadPool(10) Qwen2.5-7B · LLaMA-3.1-8BLLaMA-3.1-70B · Mistral-7BMixtral-8x22B · Gemma-2-27B max_tokens 512, temperature 0 (Gemma 0.1)cost += completion_tokens × price rewardformat · EM · cost写在最后一个 token route (≤4 轮)reply → context 第 4 轮后还没 answer:再生成一次但不再路由(final rollout, do_route=False)
一个 episode 的机制. 每一轮 policy 只做一件事:要么路由(发一个子问题给池子中的一个模型,回复以 <information> 拼回上下文),要么作答。路由最多 4 轮;第 4 轮之后若仍未作答,再生成一次但不允许路由。整条轨迹的 reward 只在最后一个 token 上给出。

这套循环(LLMGenerationManager.run_llm_loop)是从 Search-R1 继承的,Router-R1 把"调检索器"换成"调模型池"。整批样本同步推进:每一轮 vLLM 对所有仍活跃的样本生成一次,然后解析动作、统一调 API、把结果拼回去。下面四段代码是循环里的四个关键动作。

① 截断到第一个动作

vLLM 没有配置 stop token,每轮会一直生成到 1024 token 或 EOS,再在 Python 里截断到第一个 </search>(否则 </answer>),然后重新 tokenize。这意味着训练用的 token 序列并不严格等于采样出的序列(old log-prob 是在重新 tokenize 后的序列上算的,所以 PPO ratio 自洽)。

router_r1/llm_agent/generation.pyL56–L68
56    def _postprocess_responses(self, responses: torch.Tensor) -> torch.Tensor:
57        """Process responses to stop at search operation or answer operation."""
58        responses_str = self.tokenizer.batch_decode(
59            responses, 
60            skip_special_tokens=True
61        )
62
63        responses_str = [resp.split('</search>')[0] + '</search>'
64                 if '</search>' in resp
65                 else resp.split('</answer>')[0] + '</answer>'
66                 if '</answer>' in resp
67                 else resp
68                 for resp in responses_str]
只保留第一个动作:后面多写的 tag 全部丢弃。
② 解析动作

只认第一个 <search> 或 <answer>。三种路由写法被标为无效:照抄占位符 LLM-Name / Your-Query、没有冒号、冒号后为空。无效动作在环境里得到空观测,模型下一轮接着自己的输出继续写,最终靠格式奖励 −1 来惩罚。

router_r1/llm_agent/generation.pyL443–L465
443        for prediction in predictions:
444            if isinstance(prediction, str): # for llm output
445                pattern = r'<(search|answer)>(.*?)</\1>'
446                match = re.search(pattern, prediction, re.DOTALL)
447                if match:
448                    content = match.group(2).strip()  # Return only the content inside the tags
449                    action = match.group(1)
450                    if action == "search" and ("llm-name" in content.strip().lower() or "your-query" in content.strip().lower()):
451                        action = "route invalid-1"
452                    elif action == "search" and ":" not in content:
453                        action = "route invalid-2"
454                    elif action == "search" and content.strip().lower().split(":")[-1].strip() == "":
455                        action = "route invalid-3"
456                else:
457                    content = ''
458                    action = None
459            else:
460                raise ValueError(f"Invalid prediction type: {type(prediction)}")
461            
462            actions.append(action)
463            contents.append(content)
464            
465        return actions, contents
postprocess_predictions:动作 = 第一个 tag 的名字,内容 = tag 里的文本。
③ 环境步:调池子、拼回观测

所有 search 动作的子问题一次性交给 batch_route(内部是 10 线程的 API 调用)。模型名非法或 API 出错时观测是 <information>None</information>,并记 valid_action=0、成本 0。answer 动作把该样本标为 done。每个样本本轮的成本累加进 batch_completion_tokens(名字叫 tokens,实际已经乘了单价)。

router_r1/llm_agent/generation.pyL397–L423
397                if action == 'answer':
398                    next_obs.append('')
399                    dones.append(1)
400                    valid_action.append(1)
401                    is_route.append(0)
402                    cur_completion_tokens.append(0.0)
403                elif action == 'search':
404                    if route_results[0].strip().lower() == "llm name error":
405                        next_obs.append(f'\n\n<information>None</information>\n\n')
406                        route_results.pop(0)
407                        valid_action.append(0)
408                    elif route_results[0].strip().lower() == "api request error":
409                        next_obs.append(f'\n\n<information>None</information>\n\n')
410                        route_results.pop(0)
411                        valid_action.append(0)
412                    else:
413                        next_obs.append(f'\n\n<information>{route_results.pop(0).strip()}</information>\n\n')
414                        valid_action.append(1)
415                    dones.append(0)
416                    is_route.append(1)
417                    cur_completion_tokens.append(completion_tokens_list.pop(0))
418                else:
419                    next_obs.append('')
420                    dones.append(0)
421                    valid_action.append(0)
422                    is_route.append(0)
423                    cur_completion_tokens.append(0.0)
execute_predictions 的核心分支。信息两侧的空行和 .strip() 是训练时的精确格式,infer_vllm.py 用的格式和它不一样。
④ 观测截断

被调模型的回复 tokenize 后硬截到 max_obs_length=600(论文附录超参表里的 "Max Length for LLM API Response 600" 指的就是它;API 端的生成上限是 512)。硬截可能把 </information> 切掉,之后格式奖励会因 tag 不配对判 −1,这是 policy 无法控制的噪声。

router_r1/llm_agent/generation.pyL80–L94
80    def _process_next_obs(self, next_obs: List[str]) -> torch.Tensor:
81        """Process next observations from environment."""
82        
83        next_obs_ids = self.tokenizer(
84            next_obs, 
85            padding='longest',
86            return_tensors='pt',
87            add_special_tokens=False,  # Prevents adding special tokens
88        )['input_ids']
89
90        if next_obs_ids.shape[1] > self.config.max_obs_length:
91            print(f"[WARNING] OBSERVATION TOO LONG, CONSIDER CHANGING YOUR CONFIG, {next_obs_ids.shape[1]} & {self.config.max_obs_length}")            
92            next_obs_ids = next_obs_ids[:, :self.config.max_obs_length]
93
94        return next_obs_ids
观测 token 的上限;超长只打印警告。

路由池与成本记账

池子是一个 OpenAI-compatible 端点上的若干模型 id(论文用 NVIDIA NIM,id 形如 meta/llama-3.1-70b-instruct)。policy 写出的名字经宽松的子串匹配映射到 id,然后带着 AGENT_PROMPT 发一次 chat completion;返回的文本和 completion_tokens 一起回来,成本 = completion_tokens × 该模型每百万 token 的单价(没有除以 10⁶,所以单位相当于 10⁻⁶ USD;只计输出 token,不计 prompt token,也不计延迟)。

paper · Eq. (4)
Rcost ∝ − m(PLLM) · Tout

论文说 m(·) 把模型参数量映射到每 token 成本(按 API 定价档位初始化)。代码里 m 就是一张按模型 id 查的价格表:Mixtral-8x22B(1.2)比 LLaMA-70B(0.88)贵,并不严格按参数量单调。

router_r1/llm_agent/route_service.pyL79–L88
79API_PRICE_1M_TOKENS = {
80    "qwen/qwen2.5-7b-instruct": 0.3,
81    "meta/llama-3.1-70b-instruct": 0.88,
82    "meta/llama-3.1-8b-instruct": 0.18,
83    "mistralai/mistral-7b-instruct-v0.3": 0.2,
84    "mistralai/mixtral-8x22b-instruct-v0.1": 1.2,
85    "google/gemma-2-27b-it": 0.8,
86    "writer/palmyra-creative-122b": 1.8,
87    "nvidia/llama3-chatqa-1.5-8b": 0.18,
88}
价格表(USD / 1M output tokens),论文正文没有给出。最后两行是泛化实验里加入的 unseen 模型。
名字 → API id

子串匹配很宽松:任何含 "qwen" 的名字都映射到 7B 并按 0.3 计价;"llama" 必须带 8b / 70b 等尺寸,否则视为非法名。它还接受 nemotron-51b / 49b、granite 这几个不在价格表里的名字,这是一个潜在的 KeyError 崩溃点(见"坑")。

router_r1/llm_agent/route_service.pyL132–L167
132def check_llm_name(target_llm):
133    TAU = 0
134    LLM_NAME = ""
135    if "qwen" in target_llm:
136        LLM_NAME = "qwen/qwen2.5-7b-instruct"
137    elif "palmyra" in target_llm or "creative" in target_llm:
138        LLM_NAME = "writer/palmyra-creative-122b"
139    elif "llama" in target_llm:
140        if "70b" in target_llm:
141            LLM_NAME = "meta/llama-3.1-70b-instruct"
142        elif "51b" in target_llm:
143            LLM_NAME = "nvidia/llama-3.1-nemotron-51b-instruct"
144        elif "49b" in target_llm:
145            LLM_NAME = "nvidia/llama-3.3-nemotron-super-49b-v1"
146        elif "8b" in target_llm:
147            if "chatqa" in target_llm:
148                LLM_NAME = "nvidia/llama3-chatqa-1.5-8b"
149            else:
150                LLM_NAME = "meta/llama-3.1-8b-instruct"
151        else:
152            # print("!!!!!!!!!!!LLM Name Error!!!!!!!!!!!", target_llm)
153            LLM_NAME = ""
154    elif "mistral" in target_llm:
155        LLM_NAME = "mistralai/mistral-7b-instruct-v0.3"
156    elif "mixtral" in target_llm:
157        LLM_NAME = "mistralai/mixtral-8x22b-instruct-v0.1"
158    elif "granite" in target_llm:
159        LLM_NAME = "ibm/granite-3.0-8b-instruct"
160    elif "gemma" in target_llm:
161        LLM_NAME = "google/gemma-2-27b-it"
162        TAU = 0.1
163    else:
164        # print("!!!!!!!!!!!LLM Name Error!!!!!!!!!!!", target_llm)
165        LLM_NAME = ""
166
167    return LLM_NAME, TAU
check_llm_name:Gemma 用 temperature 0.1,其余 0(greedy)。做自己的池子时应换成显式 registry(规范名 → id / 单价 / 温度 / 端点)。
一次调用的成本

返回三元组 (q_id, 回复文本, 成本)。API 异常时回复是 "API Request Error"、成本 0;get_llm_response_via_api 对非超时错误最多重试 500 次、每次等 5 秒,一次限流可能卡住线程约 40 分钟。

router_r1/llm_agent/route_service.pyL110–L129
110def request_task(data):
111    q_id, query_text, TAU, LLM_NAME, api_base, api_key = data
112    if LLM_NAME == "":
113        print("LLM Name Error")
114        return q_id, "LLM Name Error", 0.0
115    print(LLM_NAME)
116    try:
117        input_prompt = AGENT_PROMPT.format_map({"query": query_text})
118        single_response, completion_tokens = get_llm_response_via_api(prompt=input_prompt,
119                                                                      base_url=api_base,
120                                                                      api_key=api_key,
121                                                                      TAU=TAU,
122                                                                      LLM_MODEL=LLM_NAME)
123        print(single_response, completion_tokens)
124    except Exception as e:
125        print(e)
126        single_response = "API Request Error"
127        completion_tokens = 0.0
128
129    return q_id, single_response, int(completion_tokens) * API_PRICE_1M_TOKENS[LLM_NAME]
第 129 行就是 m(P)·Tout。价格查表在 try 之外。

Reward 设计

三项规则奖励,论文 Eq.(2)–(5):

Eq. (2)Rformat = −1(格式错误);0(格式正确)
Eq. (3)Routcome = EM(ya, gt)
Eq. (4)Rcost ∝ − m(PLLM) · Tout,归一化到 [0, 1]
Eq. (5)rφ(x, y) = Rformat + (1 − α) Routcome + α Rcost

论文说这三项是分层的:格式奖励为 −1 时另外两项清零。主实验 α = 0(完全不看成本),成本实验扫 α ∈ {0.6, 0.7, 0.8, 0.9}。下面按代码把每一项落实。

① 格式奖励:五条硬规则

规则(Appendix A.1.2)代码检查
tag 必须成对且不能嵌套四种 tag 的开闭计数相等;任一 tag 内容里再出现 tag → nesting
以 <think> 开头、以唯一的 <answer> 结尾strip 后前 7 个字符是 <think>,</answer> 必须是最后 9 个字符
至少一个 think、恰好一个 answeranswer_enclose_count == 1,think_enclose_count > 0,think 内容不能为空或 "..."
每个 search 必须配一个 informationroute_enclose_count == info_enclose_count
路由内容必须是 "llm_name: query",名字合法、两边非空恰好一个冒号;不含占位符;query 里不能含模型名;is_valid_llm_name

代码里有 MAX / MEDIUM / SMALL 三档惩罚常量,但都等于 −1.0,所以实际只有 −1 / 0 两种取值,和论文一致。格式检查作用在整段 response(含被调模型返回的 information)上:被调模型的回复里只要出现 <answer>、<think> 字样,policy 就会被判 −1。

verl/trainer/main_ppo.pyL127–L149
127    if think_punish:
128        return PUNISH_REWARD_MAX
129
130    if is_nesting:
131        return PUNISH_REWARD_MAX
132        
133    if answer_enclose_count != 1 or think_enclose_count == 0 or route_enclose_count != info_enclose_count:
134        return PUNISH_REWARD_MAX
135
136    completion = completion.strip()
137    if not completion[:len("<think>")] == "<think>":
138        return PUNISH_REWARD_MAX
139
140    if not completion.rfind("</answer>") + 9 == len(completion):
141        return PUNISH_REWARD_MAX
142
143    if query_format_punish:
144        return PUNISH_REWARD_MEDIUM
145
146    if llm_name_punish:
147        return PUNISH_REWARD_SMALL
148
149    return 0.0
format_reward 的裁决部分(前面 L84–L124 是逐 tag 的计数与检查)。

② 结果奖励:Exact Match

答案从最后一个 <answer> 块里取出,做 SQuAD 式归一化(小写、去冠词、去标点、合并空白)后与任一 gold 完全相等记 1。训练只用 EM(+reward_metric="em");代码也支持 F1(对多个 gold 取最大 token-F1),但只用于评测。

verl/utils/reward_score/qa_em.pyL20–L47
20def normalize_answer(s):
21    def remove_articles(text):
22        return re.sub(r"\b(a|an|the)\b", " ", text)
23
24    def white_space_fix(text):
25        return " ".join(text.split())
26
27    def remove_punc(text):
28        exclude = set(string.punctuation)
29        return "".join(ch for ch in text if ch not in exclude)
30
31    def lower(text):
32        return text.lower()
33
34    return white_space_fix(remove_articles(remove_punc(lower(s))))
35
36
37def em_check(prediction, golden_answers):
38    if isinstance(golden_answers, str):
39        golden_answers = [golden_answers]
40    normalized_prediction = normalize_answer(prediction)
41    score = 0
42    for golden_answer in golden_answers:
43        golden_answer = normalize_answer(golden_answer)
44        if golden_answer == normalized_prediction:
45            score = 1
46            break
47    return score
归一化与 EM 检查,和 Search-R1 相同。

③ 成本奖励:sqrt + 滑动窗口分位归一化 + 取反

paper · Appendix A.1.3
r′ = √r,  rnorm = (r′ − rmin) / (rmax − rmin),  Rcost = 1 − clip(rnorm, 0, 1)

r 是整条轨迹所有路由调用成本之和;rmin / rmax 是最近 1000 个样本的 5 / 95 百分位;区间小于 ε 时返回中性值 0.5。于是"没有路由、成本为 0"的轨迹拿到 Rcost = 1(最大)。

verl/trainer/main_ppo.pyL36–L72
36window_size = 1000
37use_percentile = True
38q_low, q_high = 0.05, 0.95
39eps = 1e-8
40
41transform = 'sqrt'
42alpha = 0.01 
43
44buffer = deque(maxlen=window_size)
45
46
47def reward_preprocess(r: float) -> float:
48    if transform == 'log':
49        return np.log1p(alpha * r)
50    elif transform == 'sqrt':
51        return np.sqrt(r)
52    else:
53        return r
54
55
56def normalize_reward(r):
57    r = reward_preprocess(r)
58    buffer.append(r)
59    arr = np.array(buffer)
60    if use_percentile and len(arr) >= 2:
61        r_min = np.percentile(arr, 100 * q_low)
62        r_max = np.percentile(arr, 100 * q_high)
63    else:
64        r_min = arr.min()
65        r_max = arr.max()
66
67    denom = r_max - r_min
68    if denom < eps:
69        return 0.5
70
71    r_scaled = (r - r_min) / denom
72    return 1.0 - float(np.clip(r_scaled, 0.0, 1.0))
buffer 是模块级全局 deque:train 和 val 两个 RewardManager 共用,而且当前样本先入队再算分位数,同一成本的归一化值依赖历史和 batch 内顺序。第 42 行的 alpha=0.01 是未启用的 log 变换系数,不是论文的 α。

④ 组合:代码比论文更严格

论文只说 format = −1 时后两项清零。代码(EM 模式)实际是三级门控:

r = −1,格式错误
r = 0,格式正确但答错
r = (1 − α)·1 + α·Rcost,答对

cost 只在答对时才计入。这是真正防 reward hacking 的机制:答错的轨迹无论多便宜都是 0,不会出现"答错但省钱"被奖励。α > 0 时答对的轨迹 reward 落在 [1−α, 1],省钱只在"答对"内部分高下。论文的 Eq.(5) 没有写出这一层。

verl/utils/reward_score/qa_em.pyL157–L171
157                    if score == 0:
158                        return score, api_cost, score + format_score
159                    else:
160                        return score, api_cost, (score + format_score) * (1.0 - cost_coe) + api_cost * cost_coe
161            else:
162                if em_check(answer, ground_truth['target']):
163                    if format_score == -1.0:
164                        return score, api_cost, format_score
165                    else:
166                        return score, api_cost, (score + format_score) * (1.0 - cost_coe) + api_cost * cost_coe
167                else:
168                    if format_score == -1.0:
169                        return format_score, api_cost, format_score
170                    else:
171                        return format_score, api_cost, format_score
compute_score_em 训练分支的 EM 部分:第 166 行是 (score + format)·(1−α) + api_cost·α,只有 em_check 为真才会走到。
reward 落在哪里

RewardManager 只解码 response(不含 prompt),依次算格式分、路由次数、归一化成本,再调用 compute_score_em;reward、metric、cost、route_cnt 四个标量都写在最后一个有效 token 上,之后由 GAE 沿序列向前传播。验证模式额外返回 EM 与 F1 两个 metric。

verl/trainer/main_ppo.pyL237–L260
237            strict_format_score = format_reward(completion=sequences_str)
238            route_cnt = route_count(completion=sequences_str)
239
240            ground_truth = data_item.non_tensor_batch['reward_model']['ground_truth']
241
242            # API Cost Reward
243            api_cost = normalize_reward(token_price[i])
244            normalized_cost_reward.append(api_cost)
245
246            # select rm_score
247            data_source = data_item.non_tensor_batch['data_source']
248            compute_score_fn = _select_rm_score_fn(data_source)
249
250            if self.state == "train":
251                metric_score, cost_score, reward_score = compute_score_fn(solution_str=sequences_str, ground_truth=ground_truth, format_score=strict_format_score, api_cost=api_cost, state=self.state, reward_metric=self.reward_metric, cost_coe=self.cost_coe)
252                metric_tensor[i, valid_response_length - 1] = metric_score
253            else:
254                metric_score_em, metric_score_f1, cost_score, reward_score = compute_score_fn(solution_str=sequences_str, ground_truth=ground_truth, format_score=strict_format_score, api_cost=api_cost, state=self.state, reward_metric=self.reward_metric, cost_coe=self.cost_coe)
255                metric_em_tensor[i, valid_response_length - 1] = metric_score_em
256                metric_f1_tensor[i, valid_response_length - 1] = metric_score_f1
257
258            reward_tensor[i, valid_response_length - 1] = reward_score
259            cost_tensor[i, valid_response_length - 1] = cost_score
260            route_tensor[i, valid_response_length - 1] = route_cnt
训练与验证两条路径,差别只在返回的 metric 数量。

PPO 训练与 state masking

论文一句话:"外部回复(<info>)不进 loss,以保证训练稳定"。代码的做法是构造一份把 information token 全替换成 pad 的平行序列 responses_with_info_mask,由它派生出 info_mask,再作为 actor 的 loss_mask。

构造 info_mask

拼接 prompt、response、information 时同时维护两份张量:一份真实,一份把 information 换成 pad。之后"token ≠ pad"就是 mask。它依赖 pad id 不会出现在正文里(Qwen2.5 的 pad ≠ eos,安全;Llama-3.2 若 pad=eos 会出错)。

router_r1/llm_agent/generation.pyL123–L146
123    def _info_masked_concatenate_with_padding(self, 
124                prompt: torch.Tensor, 
125                prompt_with_mask: torch.Tensor, 
126                response: torch.Tensor, 
127                info: torch.Tensor = None,
128                pad_to_left: bool = True
129            ) -> torch.Tensor:
130        """Concatenate tensors and handle padding. Additionally, create a mask (info_mask) to cover the information block if it exists."""
131        pad_id = self.tokenizer.pad_token_id
132        tensors = [prompt, response]
133        tensors_with_mask = [prompt_with_mask, response]
134        if info is not None:
135            tensors.append(info)
136            info_mask = torch.full(info.size(), pad_id, dtype=info.dtype, device=info.device) # information mask
137            tensors_with_mask.append(info_mask)
138        
139        concatenated = torch.cat(tensors, dim=1)
140        concatenated_with_info = torch.cat(tensors_with_mask, dim=1)
141        mask = concatenated != pad_id if pad_to_left else concatenated == pad_id
142        sorted_indices = mask.to(torch.int64).argsort(dim=1, stable=True)
143        padded_tensor = concatenated.gather(1, sorted_indices)
144        padded_tensor_with_info = concatenated_with_info.gather(1, sorted_indices)
145
146        return padded_tensor, padded_tensor_with_info
第 136 行:information 段整体换成 pad,就是 mask 的来源。
mask 用在哪里

actor.state_masking=true 时 PPO 的 clipped surrogate 与 entropy 只在 policy 自己生成的 token 上平均;KL 惩罚同样用 info_mask。但 masking 是部分的:critic 的 value loss 与 GAE 的白化统计仍用 attention_mask,information token 上也会算 value 和 advantage(γ = λ = 1 时影响不大)。

verl/workers/actor/dp_actor.pyL237–L261
237                responses = data['responses']
238                response_length = responses.size(1)
239                attention_mask = data['attention_mask']
240                response_mask = attention_mask[:, -response_length:]
241                if self.config.state_masking:
242                    response_mask = data['loss_mask']
243                old_log_prob = data['old_log_probs']
244                advantages = data['advantages']
245
246                clip_ratio = self.config.clip_ratio
247                entropy_coeff = self.config.entropy_coeff
248
249                # all return: (bsz, response_length)
250                entropy, log_prob = self._forward_micro_batch(micro_batch=data, temperature=temperature)
251
252                pg_loss, pg_clipfrac, ppo_kl = core_algos.compute_policy_loss(old_log_prob=old_log_prob,
253                                                                              log_prob=log_prob,
254                                                                              advantages=advantages,
255                                                                              eos_mask=response_mask,
256                                                                              cliprange=clip_ratio)
257                # compute entropy loss from entropy
258                entropy_loss = verl_F.masked_mean(entropy, response_mask)
259
260                # compute policy loss
261                policy_loss = pg_loss - entropy_loss * entropy_coeff
actor 更新:response_mask = data['loss_mask']。
KL 惩罚与 PPO clip

KL 是 token 级惩罚加在 reward 上(kl_coef=0.001,fixed),不是 loss 项;clipped surrogate 是标准 PPO(clip ratio 来自 yaml 默认 0.2)。advantage 用 GAE(γ = λ = 1.0),需要 critic——这也是训练同时加载 actor、ref、critic 三份 3B 模型的原因。

verl/trainer/ppo/ray_trainer.pyL86–L104
86def apply_kl_penalty(data: DataProto, kl_ctrl: core_algos.AdaptiveKLController, kl_penalty='kl'):
87    responses = data.batch['responses']
88    response_length = responses.size(1)
89    token_level_scores = data.batch['token_level_scores']
90    batch_size = data.batch.batch_size[0]
91    attention_mask = data.batch['info_mask'] if 'info_mask' in data.batch else data.batch['attention_mask']
92    response_mask = attention_mask[:, -response_length:]
93
94    # compute kl between ref_policy and current policy
95    if 'ref_log_prob' in data.batch.keys():
96        kld = core_algos.kl_penalty(data.batch['old_log_probs'], data.batch['ref_log_prob'],
97                                    kl_penalty=kl_penalty)  # (batch_size, response_length)
98        kld = kld * response_mask
99        beta = kl_ctrl.value
100    else:
101        beta = 0
102        kld = torch.zeros_like(response_mask, dtype=torch.float32)
103
104    token_level_rewards = token_level_scores - beta * kld
apply_kl_penalty:优先用 info_mask。
verl/trainer/ppo/core_algos.pyL185–L194
185    negative_approx_kl = log_prob - old_log_prob
186    ratio = torch.exp(negative_approx_kl)
187    ppo_kl = verl_F.masked_mean(-negative_approx_kl, eos_mask)
188
189    pg_losses = -advantages * ratio
190    pg_losses2 = -advantages * torch.clamp(ratio, 1.0 - cliprange, 1.0 + cliprange)
191
192    pg_loss = verl_F.masked_mean(torch.max(pg_losses, pg_losses2), eos_mask)
193    pg_clipfrac = verl_F.masked_mean(torch.gt(pg_losses2, pg_losses).float(), eos_mask)
194    return pg_loss, pg_clipfrac, ppo_kl
标准 PPO clipped objective,eos_mask 就是上面的 loss_mask。

训练超参(train.sh / Appendix Table 8)

项值说明
policy / critic 基座Qwen2.5-3B-Instruct(或 Llama-3.2-3B-Instruct)critic 也从同一权重初始化;ref 冻结
优化器actor lr 1e-6,critic lr 1e-5,warmup 0PPO + GAE(γ = λ = 1),kl_coef 0.001
batch64 题 / step,mini-batch 32,micro-batch 8,n_agent 1每题一条轨迹;GRPO 需 n_agent > 1
步数total_training_steps 225(实际 224 次更新),save/test 每 15 步最后一个 checkpoint 是 global_step_210
长度prompt 4096 / response 1024 每轮 / start 2048 / obs 600上下文超长时从左边截,先丢的是指令和 descriptor
路由max_turns 4;API max_tokens 512,temperature 0(Gemma 0.1),seed 42第 4 轮后再生成一次但不路由
rolloutvLLM 0.6.3,TP 1,gpu_memory_utilization 0.6,temperature 1.0(train 与 eval)验证代码设了 greedy,但该设置在循环里丢失,实际也是采样
显存FSDP,actor / critic / ref 全部 param + grad + optimizer offload,gradient checkpointing,remove_padding4 卡 A6000;复现见实验 tab
rewardreward_metric em;cost_coe(α)0.0成本实验 0.6 / 0.7 / 0.8 / 0.9

与 Search-R1 的差异

论文没有正面说自己和 Search-R1 的区别。对比两个仓库(Router-R1 HEAD 801a240 vs Search-R1 main)可以精确列出:

组件Search-R1Router-R1
外部动作<search>query</search> → 检索器 HTTP 调用(Wikipedia + E5)<search>LLM-Name: query</search> → 模型池 API 调用(新文件 route_service.py)
观测top-k 文档被调模型的回复(≤600 token);非法名 / API 错误给 None;无效动作给空观测(Search-R1 会给纠正提示)
成本无每条轨迹累加 completion_tokens × 单价,经 meta_info 传给 reward;_balance_batch 重排时手动同步
rewardEM(+ 可选格式分)严格格式奖励(5 条规则)+ EM/F1 + 归一化成本奖励,α 混合,三级门控
prompt搜索指令路由指令 + 6 段 descriptor + 给被调模型的 AGENT_PROMPT
配置 / 日志search_url、topkdo_route、+reward_metric、+cost_coe、+api_base、+api_key;新增 cost / metric / route_cnt 指标,按数据源报 EM 与 F1
未改动rollout 骨架 run_llm_loop、info_mask / state masking、PPO + GAE(core_algos.py 完全相同)、tensor_helper.py 逐字节相同
结论:方法层面的新东西 = "工具从检索器换成异构 LLM 池" + "成本进 reward"。多轮交互、state masking、PPO 都是继承的。

读代码发现的坑(精选)

  1. 价格表 KeyError 会打崩 rollout。check_llm_name 接受 nemotron-51b/49b、granite,但 API_PRICE_1M_TOKENS 没有这三个 key;查价在 try 之外,policy 只要写出这类名字就会在线程池里抛异常。
  2. 子问题在第二个冒号处被截断。split(':')[1] 只取第一和第二个冒号之间;"At 10:30, who…" 实际发出的是 " At 10"。格式奖励也要求恰好一个冒号。
  3. 验证并不是 greedy。_validate 设了 do_sample=False,但 run_llm_loop 重建 DataProto 时把 meta_info 丢了,vLLM 按 temperature 1.0 采样。单次评测有方差,论文没有报告 seed 或区间。
  4. cost 只在答对时生效,且归一化依赖全局 buffer。val 的 cost 会污染训练窗口;val_only 时第一个样本恒为 0.5。日志里的 cost 是归一化后的 [0,1](越大越省),不是美元。
  5. checkpoint 路径与步数 off-by-one。225 步实际 224 次更新,最后落盘的是 global_step_210;test.sh 的 ACTOR_PATH 要自己补上这一级目录。
  6. val DataLoader drop_last=True。Bamboogle 只有 125 题,val_batch_size=500 会得到 0 个 batch 直接报错;必须设成 ≤ 数据集大小。
  7. 每轮只能一个动作、一次路由。并行子问题、多模型聚合都需要改解析器和环境步。
  8. 多模态的硬阻塞。数据集只有文本 prompt(没有 pixel_values),rollout 只传 token id,池子只发纯文本 messages,成本不计图像 / prompt token,_select_rm_score_fn 只认 7 个文本 QA 数据源。

对我们项目的启示

可以直接继承的:"policy 自己做 router"的训练框架(动作协议 + 规则奖励 + state masking + veRL),descriptor 式的零重训扩池,cost 进 reward 的做法和它的归一化细节。

必须改的:

  • Planner 的角色要重新设计。论文的反面证据很硬:先静态分解再逐个路由的 Prompt LLM* / KNN Router*(3B base)比不分解还差 0.04–0.16 EM,成本高十几倍。我们的 evidence-graph planner 不能是"先拆完再派",而要让分解本身也在 RL 回路里、能回看证据再决定下一步。
  • 动作协议要支持并行与引用。一轮多个 search、子问题引用图像 / 区域 / 前序证据;格式奖励里"恰好一个冒号"这类规则要换成 JSON 之类的结构化动作。
  • 成本要重新定义。论文只算输出 token × API 单价;我们的池子里有本地小视觉模型和 VLM,要把 prompt / 图像 token、GPU 秒、工具调用时延都计入,并做论文自己建议的 task-level normalization。
  • outcome 奖励要适配 VQA。DocVQA 的 ANLS、ChartQA 的 relaxed accuracy 等连续指标下,"答错就把 cost 清零"的门控是否还合适需要重新评估;多选题可直接用 accuracy。
  • 多轮能力要被真正用到。Router-R1 平均每题只调 1.0–1.4 次。要证明 planner + 多轮路由的价值,评测集必须是真正需要多条证据的组合式问题(见实验 tab 的数据集调研)。
实验设置

论文用的数据集:7 个纯文本 QA(训练只用两个)

数据集类型训练评测(论文)实际用的 split(FlashRAG)
NQ †general QA7,000 题(随机抽样,seed 42)500 题test(3,610 题)
TriviaQAgeneral QA—500test(11,313)
PopQAgeneral QA—500test(14,267)
HotpotQA †multi-hop7,000500dev(7,405)
2WikiMultiHopQAmulti-hop—500dev(12,576)
Musiquemulti-hop—500dev(2,417)
Bambooglemulti-hop—全集(论文写"约 120")test(125)

† in-domain。训练集 14K = NQ 7K + HotpotQA 7K;训练期 validation 用 NQ + HotpotQA 各 100 题(其中 NQ 的 100 题有 99 题也在最终 NQ 测试集的 500 题里:按 val 曲线选 checkpoint 等于在测试集上选)。所有数据集都是纯文本 QA,没有任何多模态数据。

指标

Exact Match(主表):归一化后的预测与任一 gold 完全相等。F1(附录):token 级 F1 对多个 gold 取最大,yes / no / noanswer 不匹配直接记 0。归一化 = 小写、去冠词 (a / an / the)、去标点、合并空白。答案从最后一个 <answer> 块里取。论文还报告归一化后的 cost reward(越高越省)和平均 API 调用次数。

verl/utils/reward_score/qa_em.pyL86–L119
86def f1_score(prediction: str, ground_truth: str):
87    """
88    Calculate F1 score between prediction and ground truth.
89
90    Args:
91        prediction: Predicted text
92        ground_truth: Ground truth text
93
94    Returns:
95        Tuple of (f1, precision, recall)
96    """
97    normalized_prediction = normalize_answer(prediction)
98    normalized_ground_truth = normalize_answer(ground_truth)
99
100    ZERO_METRIC = 0
101
102    if normalized_prediction in ['yes', 'no', 'noanswer'] and normalized_prediction != normalized_ground_truth:
103        return ZERO_METRIC
104    if normalized_ground_truth in ['yes', 'no', 'noanswer'] and normalized_prediction != normalized_ground_truth:
105        return ZERO_METRIC
106
107    prediction_tokens = normalized_prediction.split()
108    ground_truth_tokens = normalized_ground_truth.split()
109    common = Counter(prediction_tokens) & Counter(ground_truth_tokens)
110    num_same = sum(common.values())
111
112    if num_same == 0:
113        return ZERO_METRIC
114
115    precision = 1.0 * num_same / len(prediction_tokens)
116    recall = 1.0 * num_same / len(ground_truth_tokens)
117    f1 = (2 * precision * recall) / (precision + recall)
118
119    return f1
F1 的实现;EM 见方法 tab。

对比方法:5 个基础 + 9 个 router

  • 基础:Direct、CoT、SFT、RAG(Wikipedia-18 语料 + E5 检索)、Search-R1。
  • 单轮 router:Prompt LLM(让 base model 自己挑)、Largest LLM(永远用最大的;由附录成本表可推断实际是 Mixtral-8x22B)、KNN / MLP / BERT Router、RouterDC、GraphRouter。训练它们的监督信号是:对每道训练题让池子里每个模型多次采样,用 EM 打分,得到 (question, LLM) → 分数。
  • 分解式 router:Prompt LLM*、KNN Router*——先让 base LLM 把问题拆成子问题,再逐个路由。
  • 所有 router baseline 都被"公平化":被选中模型的输出塞回 base model 的输入,由 base model 生成最终答案,模拟 Router-R1 的聚合过程。附录 Table 5 另加了 FrugalGPT。

池子、基座与硬件

routing pool
Qwen2.5-7B-Instruct(0.3)· LLaMA-3.1-8B-Instruct(0.18)· LLaMA-3.1-70B-Instruct(0.88)· Mistral-7B-Instruct(0.2)· Mixtral-8x22B-Instruct(1.2)· Gemma-2-27B-Instruct(0.8);括号内是代码价格表的 USD / 1M output tokens,通过 NVIDIA NIM API 调用
unseen(泛化实验)
Palmyra-Creative-122B(1.8)· LLaMA3-ChatQA-1.5-8B(0.18)
policy 基座
Qwen2.5-3B-Instruct、Llama-3.2-3B-Instruct;veRL PPO,batch 64,225 步,最多 4 轮路由,α = 0.0(主实验)
硬件
NVIDIA A6000(卡数、训练时长、API 调用总量与费用均未报告)

输入、输出与 pipeline

  1. 数据准备data_process/qa_train_merge.py 从 Hugging Face 的 FlashRAG_datasets 抽样,把问题套进 prompt 模板(含 6 段 descriptor),写成 parquet;qa_test_gen.py 为每个评测集抽 500 题。
  2. rolloutvLLM 对一批 64 条 prompt 生成,每轮截到第一个动作;search 动作并发调池子 API,回复以 <information> 拼回;最多 4 轮 + 1 轮不路由的收尾。
  3. reward解码 response,算格式分(0 / −1)、EM、归一化成本、路由次数,写在最后一个 token 上。
  4. PPO 更新KL 惩罚 → GAE → critic 更新 → actor 更新(information token 被 mask)。每 15 步存 checkpoint 并跑 validation。
  5. 评测test.sh = 同一入口 + val_only=true,按数据源输出 EM / F1 / cost / route_cnt。
一条训练样本(parquet)

字段:data_source(nq / hotpotqa)、prompt(单条 user 消息,内容 = 模板 + 问题)、ability(fact-reasoning)、reward_model.ground_truth.target(gold 答案列表)、extra_info.index。我们复现时抽到的第一条 NQ 测试题:

prompt 末尾
… + You must insert your actual answer between <answer> and </answer>, following the correct format. Question: when does a wrinkle in time come out in canada?
ground truth
['March 9, 2018']
data_process/qa_train_merge.pyL69–L94
69            def process_fn(example, idx):
70                example['question'] = example['question'].strip()
71                if example['question'][-1] != '?':
72                    example['question'] += '?'
73                question = make_prefix(example, llm=model_name)
74                solution = {
75                    "target": example['golden_answers'],
76                }
77
78                data = {
79                    "data_source": data_source,
80                    "prompt": [{
81                        "role": "user",
82                        "content": question,
83                    }],
84                    "ability": "fact-reasoning",
85                    "reward_model": {
86                        "style": "rule",
87                        "ground_truth": solution
88                    },
89                    "extra_info": {
90                        'split': split,
91                        'index': idx,
92                    }
93                }
94                return data
parquet 的 schema。extra_info.index 在每个数据源内从 0 重新编号,换 GRPO 时会把 NQ 第 k 题和 HotpotQA 第 k 题并成一组。

一条轨迹长什么样

下面是我们用官方发布的 Router-R1-Qwen2.5-3B-Instruct 权重跑 infer_vllm.py、池子接到 OpenRouter 后得到的真实输出(没有任何改写):

think
To answer the question "What are the countries of the United Arab Emirates?", I need geographical knowledge about the country. I don't have this information stored within me, so I will need to consult an external specialized language model to find the answer.
information(LLaMA-3.1-70B 的回复,经 API 返回)
I'd be happy to help with that!

The United Arab Emirates (UAE) is a federation of seven emirates, not countries. These emirates are:

1. Abu Dhabi  2. Dubai  3. Sharjah  4. Ajman  5. Umm Al Quwain  6. Ras Al Khaimah  7. Fujairah

Each emirate has its own ruler, but they are all part of the UAE federation, with a president and a prime minister. The UAE is a single country, not a collection of separate countries.

If the base model needs further clarification or details about the UAE or its emirates, I'd be happy to provide more information!
answer
Abu Dhabi, Dubai, Sharjah, Ajman, Umm Al Quwain, Ras Al Khaimah, Fujairah
α = 0 的主实验 checkpoint 每一轮都选了池子里最贵的 LLaMA-3.1-70B——和附录案例研究的描述一致("无成本约束时策略收敛到几乎总是调 70B")。附录 B 里带成本约束的案例则是先问 LLaMA-3.1-8B,小模型明确说"请咨询其他 LLM"时才升级到 70B。

主结果

Exact Match:Router-R1-Qwen 对比三个最强 baseline(Qwen2.5-3B base)

数据来自 Table 1;每组只标注最高的柱

0 0.2 0.4 0.6 0.8 NQ† · Router-R1-Qwen: 0.388 0.388 NQ† · Largest LLM: 0.296 NQ† · Prompt LLM: 0.300 NQ† · Search-R1: 0.328 NQ† TriviaQA · Router-R1-Qwen: 0.706 0.706 TriviaQA · Largest LLM: 0.578 TriviaQA · Prompt LLM: 0.580 TriviaQA · Search-R1: 0.510 TriviaQA PopQA · Router-R1-Qwen: 0.384 0.384 PopQA · Largest LLM: 0.354 PopQA · Prompt LLM: 0.340 PopQA · Search-R1: 0.324 PopQA HpQA† · Router-R1-Qwen: 0.352 0.352 HpQA† · Largest LLM: 0.278 HpQA† · Prompt LLM: 0.268 HpQA† · Search-R1: 0.236 HpQA† 2wiki · Router-R1-Qwen: 0.434 0.434 2wiki · Largest LLM: 0.274 2wiki · Prompt LLM: 0.262 2wiki · Search-R1: 0.278 2wiki Musique · Router-R1-Qwen: 0.138 0.138 Musique · Largest LLM: 0.104 Musique · Prompt LLM: 0.108 Musique · Search-R1: 0.090 Musique Bamb · Router-R1-Qwen: 0.512 0.512 Bamb · Largest LLM: 0.480 Bamb · Prompt LLM: 0.448 Bamb · Search-R1: 0.272 Bamb
Router-R1-QwenLargest LLMPrompt LLMSearch-R1

2wiki 的领先最大(0.434 vs 0.278);Musique 对所有方法都难(≤0.138)。

MethodNQ†TriviaQAPopQAHpQA†2wikiMusiqueBambAvg.
Qwen2.5-3B-Instruct
Direct0.0920.2600.1220.1400.2660.0260.0400.135
CoT0.1260.3580.1600.1680.2080.0460.2240.184
SFT0.2120.4000.1600.1980.2560.0520.1120.199
RAG0.2980.5400.3660.2160.1460.0780.2240.267
Search-R10.3280.5100.3240.2360.2780.0900.2720.291
Prompt LLM0.3000.5800.3400.2680.2620.1080.4480.329
Largest LLM0.2960.5780.3540.2780.2740.1040.4800.338
KNN Router0.2620.5280.2220.2240.1960.0660.3600.265
MLP Router0.2520.4600.2220.1980.2100.0720.3600.253
BERT Router0.2300.5160.1920.2160.2060.0580.3120.247
RouterDC0.2780.5920.2820.2440.2180.0800.5040.314
GraphRouter0.2760.5860.2800.2340.1800.0760.4480.297
Prompt LLM*0.2580.5000.2560.2060.2480.0780.4720.288
KNN Router*0.2360.4780.2320.1540.2340.0720.3840.256
Router-R1-Qwen0.3880.7060.3840.3520.4340.1380.5120.416
Llama-3.2-3B-Instruct
Direct0.2020.3280.1760.1440.1340.0180.0480.150
CoT0.2560.4680.1820.1720.1680.0400.2720.223
SFT0.0760.0980.0840.1000.2240.0260.0160.089
RAG0.3080.4780.3560.1620.0840.0380.1760.229
Search-R10.3720.5780.3600.2820.2260.0840.2720.311
Prompt LLM0.3040.6380.3740.2480.1980.1320.5280.346
Largest LLM0.3440.6160.3940.2580.2420.1220.4720.350
KNN Router0.2920.5720.2540.2100.1820.0780.3760.281
MLP Router0.2820.5060.2480.1780.1880.0640.3600.261
BERT Router0.2560.5600.2220.2100.1880.0660.2960.257
RouterDC0.3100.6140.2980.2500.2040.0880.5040.324
GraphRouter0.3160.6020.2900.2220.1700.0840.4160.300
Prompt LLM*0.2360.4460.1640.1180.0800.0360.2080.184
KNN Router*0.2020.3980.1660.0960.0600.0300.1760.161
Router-R1-Llama0.4160.6800.4320.3220.3680.1280.5200.409

Table 1(论文 p.8):7 个 QA 数据集上的 Exact Match。加粗 = 该 base model 下每列最高;† = in-domain(训练集只含 NQ 与 HotpotQA)。

读表要点。Router-R1-Qwen 平均 EM 0.416,七列全部最高;Router-R1-Llama 0.409,但在 Musique(0.128 vs Prompt LLM 0.132)和 Bamboogle(0.520 vs 0.528)输给 Prompt LLM。最强 baseline 不是 Search-R1(0.291 / 0.311)而是"直接交给大模型"的 Largest LLM(0.338 / 0.350)和 Prompt LLM(0.329 / 0.346)。提升主要来自多跳:2wiki 上 Qwen 版 0.434 vs 第二名 0.278。分解式 router(带 *)反而比不分解更差(Qwen:0.288 / 0.256 vs 0.329 / 0.265;Llama 更惨),而且成本高十几倍。SFT 在 Llama 上崩到 0.089,论文没有解释。所有数字都是单次运行、500 题子集、采样温度 1.0,没有方差。

F1(附录 Table 3)

Method (F1)NQ†TriviaQAPopQAHpQA†2wikiMusiqueBambAvg.
Qwen2.5-3B-Instruct
Direct0.1620.3410.1540.2150.3040.0810.1120.196
CoT0.2180.4310.1850.2600.2510.1060.3320.255
SFT0.2890.4600.2070.2810.2910.1210.1730.260
RAG0.4140.6220.4520.3070.1870.1340.3030.346
Search-R10.4070.5750.3830.3280.3170.1450.3870.363
Prompt LLM0.4370.6940.4090.4070.3930.2050.5790.446
Largest LLM0.4310.6950.4230.4160.3970.1990.6080.453
KNN Router0.3880.6270.2810.3410.2890.1410.4960.366
MLP Router0.3680.5570.2720.2950.2770.1420.4600.339
BERT Router0.3620.6350.2510.3350.2840.1350.4230.346
RouterDC0.4100.6940.3280.3810.2930.1650.6230.413
GraphRouter0.4120.6900.3240.3660.2580.1540.5460.393
Prompt LLM*0.3730.6000.3150.3130.3550.1650.5800.386
KNN Router*0.3600.5720.2720.2480.2990.1380.4930.340
Router-R1-Qwen0.4840.7720.4470.4490.4870.2120.6350.498
Llama-3.2-3B-Instruct
Direct0.2810.3770.2090.2110.1650.0700.0970.201
CoT0.3640.5340.2300.2410.2130.1040.3850.296
SFT0.1250.1590.1170.1540.2670.0750.0420.134
RAG0.4100.5570.4130.2470.1190.0700.2400.294
Search-R10.4780.6500.4120.3750.2710.1380.3370.380
Prompt LLM0.4500.7330.4410.3690.3010.2220.6280.449
Largest LLM0.4690.7110.4480.3770.3410.2040.5630.445
KNN Router0.4100.6510.2920.3120.2480.1400.5040.365
MLP Router0.3950.5850.2900.2710.2360.1340.4550.338
BERT Router0.3830.6560.2720.3100.2440.1260.3880.340
RouterDC0.4350.7080.3380.3710.2570.1610.6010.410
GraphRouter0.4410.7040.3270.3430.2270.1460.5450.390
Prompt LLM*0.3420.5240.2090.1880.1360.0880.3020.256
KNN Router*0.3110.4760.2110.1490.1040.0740.2590.226
Router-R1-Llama0.5200.7400.4610.4290.4200.1880.6250.483

Table 3(附录 p.15):同一设置下的 F1。注意 Qwen 的 PopQA 列论文加粗了 Router-R1 的 0.447,但 RAG 是 0.452。

成本–性能权衡

主实验 α = 0 时 Router-R1 很贵:NQ 上 raw cost 150.6,几乎等于单独调用 LLaMA-3.1-70B(153.3),而 Largest LLM 只要 20.2。成本实验在 Qwen base 上扫 α ∈ {0.6, 0.7, 0.8, 0.9}(没有 0 到 0.6 之间的点):

EM 随成本系数 α 的变化(Router-R1-Qwen)

数据来自 Table 4;α=0.0 是主实验 checkpoint

0.150 0.225 0.300 0.375 0.450 α=0.0 α=0.6 α=0.7 α=0.8 α=0.9 cost coefficient α NQ @ α=0.0: 0.388 NQ @ α=0.6: 0.388 NQ @ α=0.7: 0.318 NQ @ α=0.8: 0.320 NQ @ α=0.9: 0.244 PopQA @ α=0.0: 0.384 PopQA @ α=0.6: 0.414 PopQA @ α=0.7: 0.280 PopQA @ α=0.8: 0.270 PopQA @ α=0.9: 0.234 HpQA @ α=0.0: 0.352 HpQA @ α=0.6: 0.332 HpQA @ α=0.7: 0.254 HpQA @ α=0.8: 0.238 HpQA @ α=0.9: 0.186 2wiki @ α=0.0: 0.434 2wiki @ α=0.6: 0.422 2wiki @ α=0.7: 0.236 2wiki @ α=0.8: 0.202 2wiki @ α=0.9: 0.252
NQPopQAHpQA2wiki

0.6 → 0.7 是断崖:EM 掉 0.07–0.19;0.9 时 2wiki 反而回升到 0.252。

Raw cost 随 α 的变化(Router-R1-Qwen)

数据来自 Table 4;越低越省

0 40 80 120 160 α=0.0 α=0.6 α=0.7 α=0.8 α=0.9 cost coefficient α NQ @ α=0.0: 151 NQ @ α=0.6: 150 NQ @ α=0.7: 32 NQ @ α=0.8: 29 NQ @ α=0.9: 6 PopQA @ α=0.0: 98 PopQA @ α=0.6: 76 PopQA @ α=0.7: 17 PopQA @ α=0.8: 15 PopQA @ α=0.9: 5 HpQA @ α=0.0: 139 HpQA @ α=0.6: 124 HpQA @ α=0.7: 27 HpQA @ α=0.8: 28 HpQA @ α=0.9: 5 2wiki @ α=0.0: 151 2wiki @ α=0.6: 114 2wiki @ α=0.7: 31 2wiki @ α=0.8: 31 2wiki @ α=0.9: 6
NQPopQAHpQA2wiki

α=0.0 时 NQ 成本 150.6 ≈ 单独调用 LLaMA-3.1-70B(153.3);α=0.9 降到 5.5,低于任何单模型。

Method (Qwen2.5-3B base)NQ† EMCostPopQA EMCostHpQA† EMCost2wiki EMCost
Qwen2.5-3B-Instruct
Prompt LLM0.30020.00.34017.60.26820.10.26220.2
Largest LLM0.29620.20.35417.60.27820.10.27420.1
KNN Router0.26241.00.22230.30.22445.40.19651.8
MLP Router0.25235.80.22221.00.19829.50.21041.3
BERT Router0.23026.00.19216.30.21626.00.20626.3
RouterDC0.27857.50.28221.80.24462.30.21840.7
GraphRouter0.27629.60.28019.20.23424.70.18028.6
Prompt LLM*0.258286.40.256111.70.206313.40.248222.4
KNN Router*0.236102.20.23249.80.154133.00.23499.4
Qwen2.5-7B-Instruct0.13824.20.13018.60.15224.90.16628.7
LLaMA-3.1-70B-Instruct0.280153.30.34276.30.260124.60.270119.8
LLaMA-3.1-8B-Instruct0.24229.50.20814.30.19824.10.13021.3
Mistral-7B-Instruct0.19220.20.18216.20.20219.10.19818.3
Mixtral-8x22B-Instruct0.29620.20.35417.60.27820.10.27420.1
Gemma-2-27B-Instruct0.28242.70.29022.00.24437.80.19044.6
Router-R1-Qwen (α=0.0)0.388150.60.38498.30.352138.60.434150.8
Router-R1-Qwen (α=0.6)0.388150.00.41475.90.332124.30.422113.8
Router-R1-Qwen (α=0.7)0.31832.30.28017.20.25427.20.23631.4
Router-R1-Qwen (α=0.8)0.32028.90.27014.90.23828.20.20231.4
Router-R1-Qwen (α=0.9)0.2445.50.2345.30.1865.30.2526.5

Table 4(附录 p.16):EM 与 raw cost(未归一化;按代码口径 = Σ completion_tokens × 单价(USD/1M),单位相当于 10⁻⁶ USD)。中段 6 行是直接单独调用池子里每个模型。Largest LLM 一行与 Mixtral-8x22B 一行逐格相同。

  • α = 0.6 几乎不掉点(NQ 0.388 = 0.388;PopQA 0.414 反而高于 0.384),成本小幅下降(PopQA 98.3 → 75.9,2wiki 150.8 → 113.8)。论文称 0.6 "consistently achieves a favorable balance"。
  • 0.6 → 0.7 是相变:EM 掉 0.07–0.19,成本降到约五分之一;0.7 与 0.8 几乎重合;0.9 成本只有 5.3–6.5(比任何单模型都低),EM 0.19–0.25。
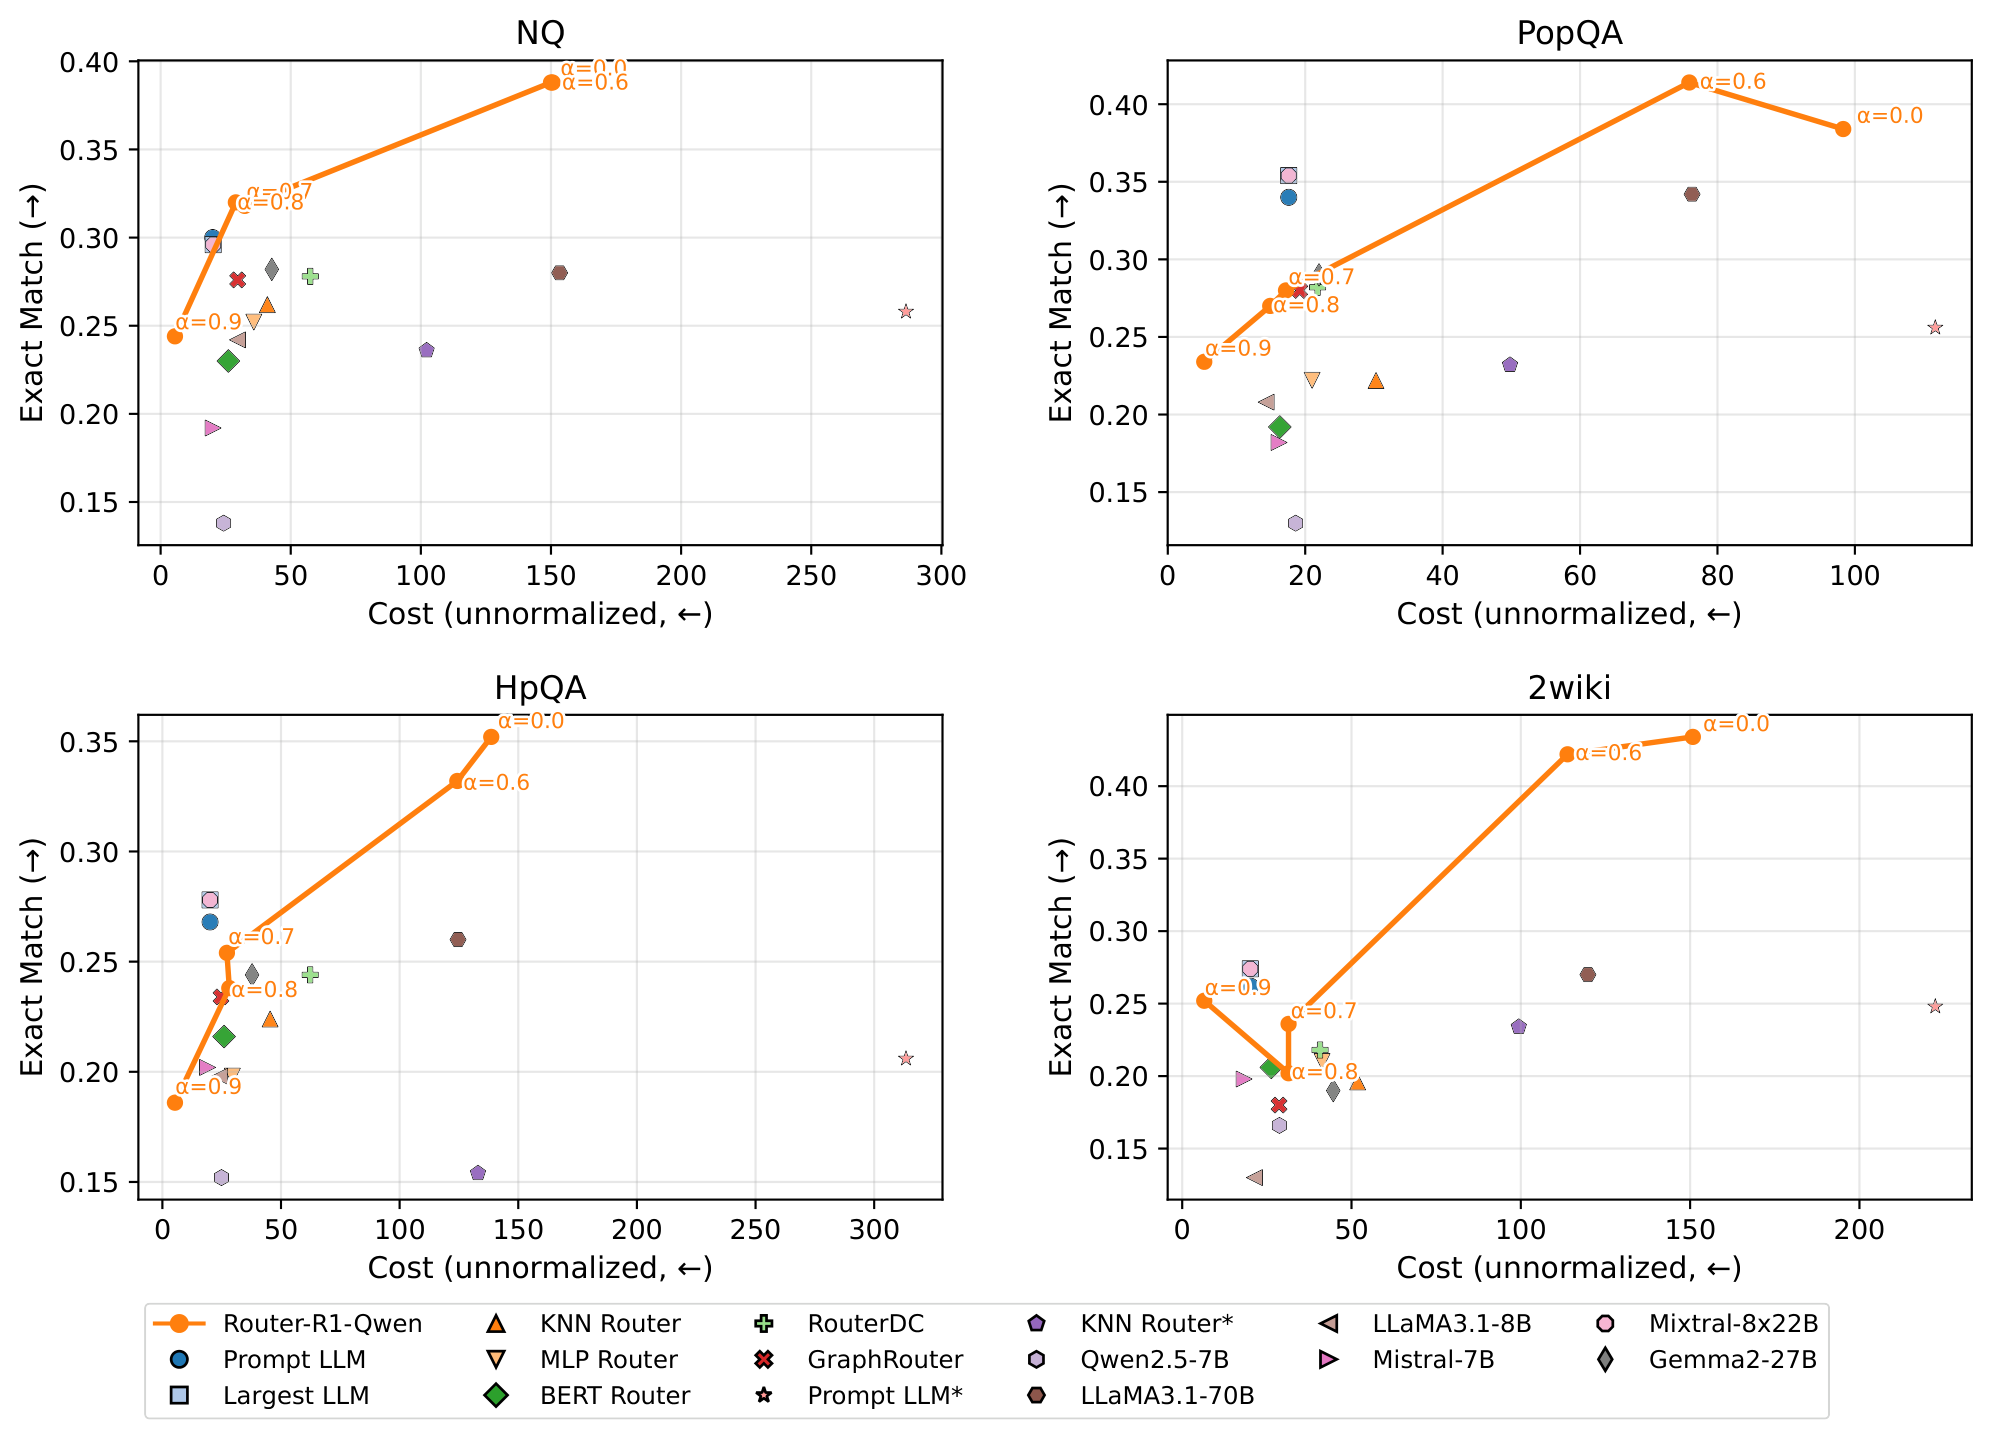
  • 便宜端并不占优。附录 Figure 5 的 Pareto 图里,α = 0.7 / 0.8 的点在 PopQA、HpQA、2wiki 上被单独调用 Mixtral-8x22B(EM 0.354 / 0.278 / 0.274,成本约 20)压住;Router-R1 真正占据的是高精度端。Mixtral 单价最高却成本最低,论文归因于它回答更短。
  • 涌现的级联策略:有成本约束时 policy 先问小模型、失败再升级,形成"小模型优先、必要时升级"的自适应路由。
Pareto scatter of EM versus raw cost on four datasets; the Router-R1 alpha curve spans from very low cost to the highest accuracy
Figure 5(附录). 四个数据集上的 cost–EM 散点,折线连接 Router-R1-Qwen 的 5 个 α。α 曲线覆盖从极低成本到最高精度的前沿,但低成本区间与 Largest LLM / Mixtral 重合。

泛化到新模型

不重训,只把两个 unseen 模型的 descriptor 加进 prompt(Palmyra-Creative-122B 是创意写作模型,基本是干扰项;LLaMA3-ChatQA-1.5-8B 是对话 QA 模型),在 4 个数据集上比较:

MethodNQ† EMF1TriviaQA EMF1PopQA EMF1HpQA† EMF1Avg EMAvg F1
Prompt LLM0.3000.4370.5800.6940.3400.4090.2680.4070.3720.487
Prompt LLM‡0.2960.4330.5840.6970.3420.4120.2660.4090.3720.488
BERT Router0.2300.3620.5160.6350.1920.2510.2160.3350.2890.396
BERT Router‡0.2380.3700.5500.6620.2360.3230.1980.3220.3060.419
GraphRouter0.2760.4120.5860.6900.2800.3240.2340.3660.3440.448
GraphRouter‡0.2820.4200.5940.6960.2760.3220.2280.3600.3450.450
Prompt LLM*0.2580.3730.5000.6000.2560.3150.2060.3130.3050.400
Prompt LLM*‡0.2120.3110.4400.5410.1960.2470.1660.2520.2540.338
Router-R1-Qwen0.3880.4840.7060.7720.3840.4470.3520.4490.4580.538
Router-R1-Qwen‡0.3820.4930.7220.7780.4020.4640.3460.4590.4630.549

Table 2(论文 p.10):‡ = 推理时把 Palmyra-Creative-122B 和 LLaMA3-ChatQA-1.5-8B 加进池子(只加 descriptor,不重训)。Avg 只在这 4 个数据集上平均,不能与 Table 1 的 7 数据集平均直接比。

Router-R1-Qwen 平均 EM 0.458 → 0.463(+0.005)、F1 0.538 → 0.549;但 NQ 的 EM 0.388 → 0.382、HpQA 0.352 → 0.346 略降,论文"四个基准都维持甚至略升"的说法只对 F1 成立。对比里 Prompt LLM* 加新模型后掉了 0.051,而 BERT Router 的提升(+0.017)其实比 Router-R1 大。新模型被实际调用了多少次论文没有报告;提升幅度在单次运行的噪声范围内。

训练动态与调用次数

每题平均 API 调用次数(Router-R1-Qwen,Figure 4a)

上限是 4 轮;读自论文图

0 0.5 1 1.5 NQ† · avg LLM calls: 1.06 1.06 NQ† TriviaQA · avg LLM calls: 1.01 1.01 TriviaQA PopQA · avg LLM calls: 1.17 1.17 PopQA HpQA† · avg LLM calls: 1.12 1.12 HpQA† 2wiki · avg LLM calls: 1.29 1.29 2wiki Musique · avg LLM calls: 1.36 1.36 Musique Bamb · avg LLM calls: 1.06 1.06 Bamb

平均只有 1.01–1.36 次调用:所谓 multi-round 绝大多数情况下是一轮。

Training reward curves with and without format reward
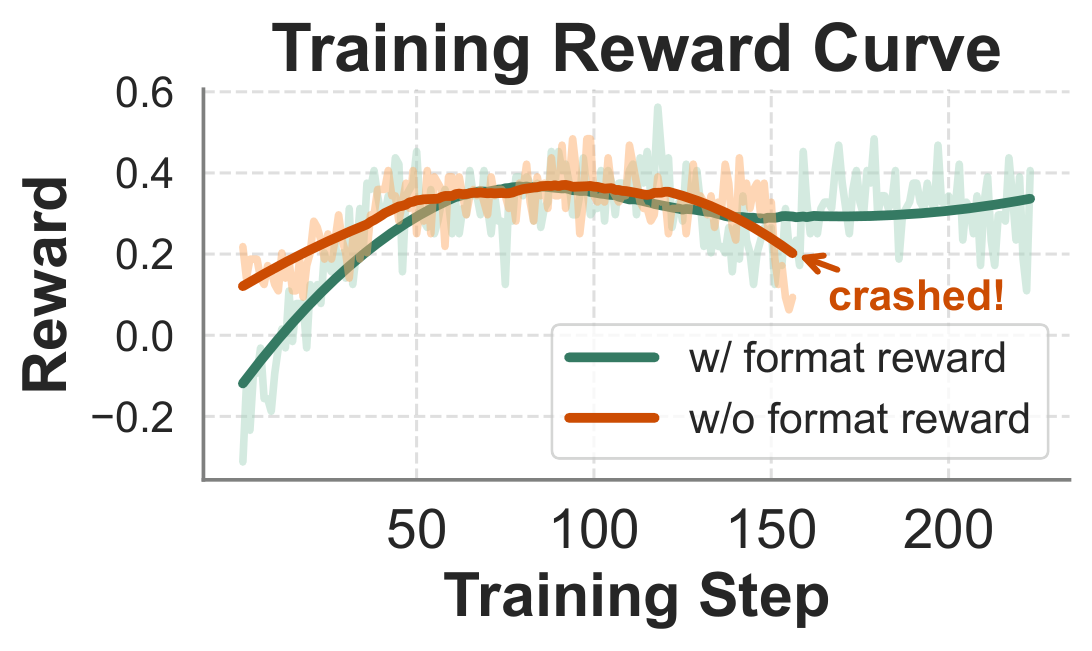
Figure 4b. 有格式奖励(绿)时 reward 从约 −0.12 升到 0.37 附近(step 80–100)后稳定在 0.3 左右;没有格式奖励(橙)起点更高(没有 −1 惩罚),但在约 step 155 崩溃。
Policy entropy curves with and without format reward
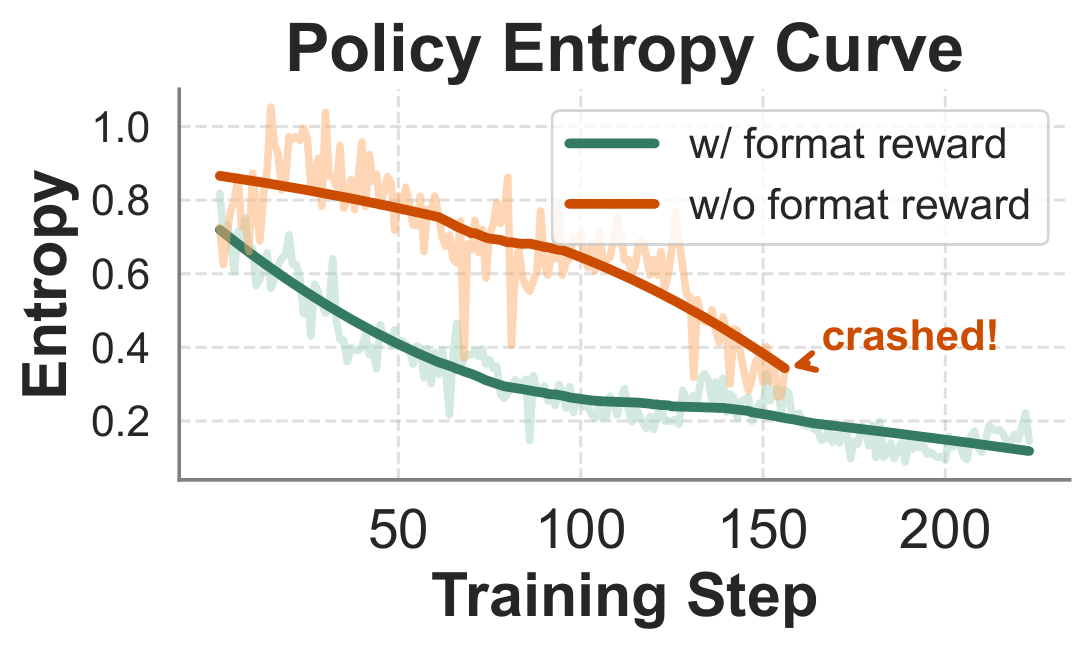
Figure 4c. policy entropy 从约 0.72 降到 0.12;无格式奖励时更高更噪(0.87 → 0.35)直到崩溃。论文结论:格式奖励(及其分层清零)是训练稳定的关键;约 100 步收敛。
每题平均只路由 1.01–1.36 次(上限 4)。多跳集(2wiki 1.29、Musique 1.36)略多,但 Bamboogle(1.06)和 NQ 一样低。换句话说,Router-R1 的收益大部分来自"学会把问题交给合适的大模型再自己聚合",多轮能力几乎没被用到;论文也没有做限制轮数的消融。

消融与附加实验(附录)

实验设置Avg EM说明
默认Router-R1-Qwen,6 模型池,α = 00.416Table 1
FrugalGPT baseline级联式 router,同一 base0.318七个数据集全部落后(Table 5)
压缩 descriptor每个模型只留一句话0.419descriptor 丰富度几乎不影响结果(Table 6)
训练期扩池+ LLaMA3-ChatQA-1.5-8B(7 模型)0.425Bamb 0.512 → 0.568、Musique 0.138 → 0.154;HpQA 0.352 → 0.332、2wiki 0.434 → 0.421(Table 7)
去掉格式奖励只看训练曲线—约 step 155 崩溃,无测试 EM(Figure 4b/4c)

没有做的消融:分层门控、路由轮数上限、PPO vs GRPO、单轮 vs 多轮 Router-R1、训练数据配比、Llama base 的成本实验。

复现记录(2026-10-31,进行中)

目标:用官方权重和代码在我们的集群上先跑通推理与评测,再做短训练验证 reward 曲线。环境:一张 48 GB 的 L40S(共享集群),复用一套与仓库要求一致的 Python 3.9 / torch 2.4 / vLLM 0.6.3 / transformers 4.47 / flash-attn 2.8 环境,直接从仓库根目录运行(使用仓库自带的 verl)。

阶段内容状态结果 / 备注
0 数据三个 data_process 脚本(NQ + HotpotQA)✓train 14,000 行、val 200 行、NQ test 500 行;prompt 与 ground truth 结构如上
1 单题推理infer_vllm.py + 发布的 Qwen 权重(fp32 safetensors 13 GB)✓(dry-run)vLLM 加载正常;输出严格符合 think / search 格式,5 轮全部选 LLaMA-3.1-70B;池子未接通所以没有最终答案
2 评测test.sh(val_only)NQ 500 题,1 卡✗ → 修复中ray / FSDP(actor + critic + ref)/ vLLM 引擎都初始化成功,在第一次 rollout 把 FSDP 权重同步进 vLLM 时 OOM:fp32 actor 常驻 12 GB + 聚合的 state dict 12 GB + vLLM 预留 + 模型拷贝 > 44 GB。已把权重转成 bf16、vLLM 预留降到 0.3 仍 OOM(43 GB);下一步用 2 卡(FSDP 分片后每卡减半)或绕过 verl 直接用 vLLM 批量评测
2b 真实评测(NQ)单卡批量评测器(vLLM + 仓库 reward 函数)+ OpenRouter 池子,temperature 1.0(与论文评测一致)✓EM 0.380 / F1 0.496,平均 1.04 次调用,raw cost 148.0,格式正确率 98.6%;论文 Table 1/3/4:EM 0.388 / F1 0.484 / 1.06 次 / 150.6。500 题在一张 L40S 上 4.5 分钟(其中 API 调用约 4 分钟),API 费用不到 $0.2。dry 模式(无信息)时 EM 只有 0.078,说明分数几乎全部来自路由到池子的 70B
2c 全部 7 个集同一评测器,两张卡并行(L40S + RTX 6000 Ada),detached 运行✓见下表:7 集平均 EM 0.424(论文 0.416),每集都在论文 ±0.03 内;逐题轨迹在 W&B(project 26icml,group router-r1)
3 短训练train.sh 15–30 步,2–4 卡待需要池子 API 额度:每步 64 题 × ≤4 次调用 × ~300 token

复现结果:7 个数据集

复现 vs 论文:Router-R1-Qwen 在 7 个 QA 集上的 EM

同一权重、同一评测口径;差异 ≤ 0.03

0 0.2 0.4 0.6 0.8 NQ† · 复现 EM: 0.380 0.380 NQ† · 论文 EM: 0.388 NQ† TriviaQA · 复现 EM: 0.710 0.710 TriviaQA · 论文 EM: 0.706 TriviaQA PopQA · 复现 EM: 0.392 0.392 PopQA · 论文 EM: 0.384 PopQA HpQA† · 复现 EM: 0.370 0.370 HpQA† · 论文 EM: 0.352 HpQA† 2wiki · 复现 EM: 0.422 0.422 2wiki · 论文 EM: 0.434 2wiki Musique · 复现 EM: 0.150 0.150 Musique · 论文 EM: 0.138 Musique Bamb · 复现 EM: 0.544 0.544 Bamb · 论文 EM: 0.512 Bamb
复现 EM论文 EM

7 集平均:复现 0.424 vs 论文 0.416。

数据集题数EM 复现EM 论文F1 复现F1 论文调用/题 复现论文raw cost 复现论文格式正确率run
NQ†5000.3800.3880.4960.4841.041.06148.0150.60.986W&B
TriviaQA5000.7100.7060.7850.7721.001.0189.9—0.984W&B
PopQA5000.3920.3840.4560.4471.161.17104.298.30.964W&B
HpQA†5000.3700.3520.4800.4491.111.12141.6138.60.976W&B
2wiki5000.4220.4340.4820.4871.241.29146.2150.80.976W&B
Musique5000.1500.1380.2150.2121.391.36228.5—0.972W&B
Bamb1250.5440.5120.6560.6351.021.06109.8—1.000W&B
Avg (7)3,1250.4240.4160.5100.4981.141.15138.3—0.980

复现:官方 Router-R1-Qwen2.5-3B-Instruct 权重,池子经 OpenRouter(Mistral-7B-v0.3 用 ministral-8b-2512 代替),temperature 1.0 单次运行,每集随机 500 题(Bamboogle 全集 125);与论文一样是单次采样,所以 ±0.02 的差异在噪声范围内。论文列:Table 1(EM)、Table 3(F1)、Figure 4a(调用次数)、Table 4(raw cost,只有 4 个集)。

池子 API 的替换

仓库的模型 id 是 NVIDIA NIM 风格,我们没有 NIM 账号。工作副本加了一个由环境变量选择的 id 映射,把上游 id 映射到 OpenRouter 的 id,成本仍按上游价格表计,所以成本数字可与论文比较;Mistral-7B-Instruct-v0.3 已从 OpenRouter 下架,用 ministral-8b-2512 代替(结果里需标注)。另加了一个 dry 模式:不调 API、立即返回占位信息,用来在没有额度时验证整条 rollout 链路(也避开了仓库里"API 出错重试 500 次 × 5 秒"的死循环)。

route_service.py(工作副本补丁)节选
1PROVIDER_IDS = {
2    "openrouter": {
3        "qwen/qwen2.5-7b-instruct": "qwen/qwen-2.5-7b-instruct",
4        "meta/llama-3.1-70b-instruct": "meta-llama/llama-3.1-70b-instruct",
5        "meta/llama-3.1-8b-instruct": "meta-llama/llama-3.1-8b-instruct",
6        "mistralai/mistral-7b-instruct-v0.3": "mistralai/ministral-8b-2512",   # v0.3 已下架,代替品
7        "mistralai/mixtral-8x22b-instruct-v0.1": "mistralai/mixtral-8x22b-instruct",
8        "google/gemma-2-27b-it": "google/gemma-2-27b-it",
9    },
10}
11
12def provider_model_id(upstream_id):
13    return PROVIDER_IDS.get(POOL_PROVIDER, {}).get(upstream_id, upstream_id)

当前阻塞:OpenRouter 与 OpenAI 的 key 都没有余额。按 OpenRouter 价格估算,7 个数据集的完整评测(约 3,500 题 × 1–1.4 次调用 × ~300 token)不到 3 美元,20 步短训练约 5–10 美元。备选:用本地 vLLM 起一个缩减池(Qwen2.5-7B、LLaMA-3.1-8B 已在缓存,Mistral-7B / Gemma-27B 可下,70B 与 8x22B 需要多卡或量化)。

下一步:换成 VQA

Router-R1 的全部实验都是纯文本 QA。我们项目的目标是多模态 VQA / 多模态 RAG:52 个候选 VQA 数据集的逐条核实与推荐方案见页顶第三个 tab 「3 · VQA 数据集」。

VQA 数据集调研

这里的每一个数据集都以图像、文档页、图表、信息图、幻灯片或屏幕截图作为输入的一部分(不是纯文本 QA)。按七个家族各自搜索候选,再对每个数据集独立打开官方页面 / 论文 / Hugging Face 卡片核实年份、会议、规模、答案形式、指标、许可、训练集与测试标签是否公开、是否自带检索语料,共 51 个(53 条核实记录,两个数据集被两个家族各核实一遍后合并),每个附核实备注;核实置信度不足 0.6 的标 ⚠。

对 planner + cost-aware router 项目最重要的四个判断:① 问题是否真的需要分解 / 检索 / 看图(否则 planner 和多轮路由没有用武之地);② gold 答案能否规则判分(RL 需要 EM / F1 / ANLS / relaxed accuracy / 多选 accuracy);③ 有没有公开训练集;④ 测试标签是否公开(否则只能用 val)。

51VQA 数据集(53 条核实记录)7家族14知识密集 / 实体型8文档 / 图表 / 信息图7多跳 / 组合式7OCR / 场景文字8专家推理8通用 / 组合式基线
家族代表数据集对我们的意义
知识密集 / 实体型 VQAEncyclopedic-VQA, InfoSeek, OK-VQA, A-OKVQA, ViQuAE, KVQA, FVQA (MMSearch-R1), Dyn-VQA问题要先认出图里的实体再查知识:天然需要「视觉模型识别 → 文本检索 / LLM 作答」的路由。
多跳 / 组合式多模态 QAMultimodalQA, WebQA, M3DocVQA, CRAG-MM, VisDoM, MMCoQA, SlideVQA一题要跨文本 / 表格 / 图像多条证据:最接近「证据依赖图」的分解设定。
文档 / 图表 / 信息图DocVQA, MP-DocVQA, InfographicVQA, ChartQA, ChartQAPro, DUDE, TAT-DQA, MMLongBench-Doc用户点名的方向;答案多为短 span / 数值,ANLS / relaxed accuracy 可规则判分;OCR 小模型 vs VLM 的成本差异明显。
OCR / 场景文字TextVQA, ST-VQA, OCR-VQA, Text-KVQA, WebSRC, ScreenQA, OCRBench v2检验「便宜的 OCR 工具 + LLM」能否替代昂贵 VLM。
专家级推理MMMU, MMMU-Pro, MathVista, MATH-Vision, ScienceQA, M3CoT, EMMA, MMK12多选 / 数值答案,accuracy 可规则判分;考验路由到强模型的收益。
通用 / 组合式基线VQA v2, GQA, CLEVR, Visual7W 类, VizWiz, MMBench, MMStar, SEED-Benchsanity check 与大规模训练信号;大多数不需要检索。
多模态搜索 / 浏览(长程)MMSearch, MMSearch-Plus, BrowseComp-VL, MM-BrowseComp, LiveVQA, MTA-Vision-DeepSearch需要迭代搜索直到预算用尽,正对应「cost 到阈值就停」的设计;多为 eval-only、LLM judge。

推荐方案(综合稿结论,供讨论)

结论来自逐条核实后的综合稿 VQA数据集调研_2026-10-31.md(118 KB,含 377 条来源链接)。原则:对标 Router-R1 的「NQ 7K + HotpotQA 7K 训练、7 个集评测」,挑有公开 train split、短答案、官方规则评分脚本的集合做 RL 训练;评测再加 OOD 的知识检索、开放域文档检索、agentic 搜索和困难图表。

RL 训练混合(对标 NQ + HotpotQA)

数据集对标可用 trainreward 口径(官方脚本)为什么进主要风险
MultimodalQA (MMQA) · ICLR 2021HotpotQAtrain 23,817;dev 2,441 当 testlist EM / list F1(DROP 式列表对齐)16 类 compositional 题型(Compose / Compare / Intersect 组合文本 / 表格 / 图像子问题),每题自带 gold type program = 现成的证据依赖链,可监督 / 评估 planner;答案标 modality,router 选池有明确依据test 无答案,dev 兼作 test;license 未写明
Encyclopedic-VQA · ICCV 2023NQtrain 212,338;test 5,750 公开官方 EM(VQA 式归一化),multi-answer 用集合 IoU ≥ 0.5实体识别 → 2M 篇 Wikipedia KB 的 section 检索 → 读答案,三步 cost 差异大;2_hop 子集(21K)天然 A→B;带 evidence section id,可单测检索子步数据 license 未写明;图像要从 iNat21 / GLDv2 自行下载(数百 GB)
TAT-DQA · ACM MM 2022新增:文档 + 数值train 13,251;test 1,662 gold 公开EM + numeracy F1(scale / 正负号敏感)42% 是算术题,天然拆成「定位单元格 A、B → 计算」:版面定位给 OCR / 小 VLM,算术给 text LLM 或 code 工具;CC BY 4.0只有财报域;平均 1.33 页,几乎无跨页检索
可选第 4 ChartQA · Findings ACL 2022新增:charttrain 28,299;test 2,500 公开relaxed accuracy(数值 5% 容差)H 题 76% 是组合 / 视觉组合推理,可拆成「读 series → 比较 / 算术」;带 CSV 表,可构造「小模型 chart-to-table + LLM」vs「大 VLM 直答」两条 cost 路径只有 bar / line / pie;GPL-3.0
  • 采样建议:MMQA 7K(按 16 类分层)+ E-VQA 7K(按 question_type 分层,过采样 2_hop 与 multi_answer)+ TAT-DQA 5K(算术 / span 各半)+ ChartQA-H 全部 7,398 或抽 3K,总量约 2 万,与 Router-R1 的 1.4 万同量级;每条带 data_source,reward 按来源分派(Router-R1 的 _select_rm_score_fn 就是这么做的)。
  • 知识集的替代:若 E-VQA 的 license 不明是硬伤,换 InfoSeek(Apache-2.0,train 934K,Wiki6M KB,别名 / 数值区间可规则判分);代价是 test 无公开答案、图像需走 OVEN 下载或 294 GB gated 快照。两者都用也可以。
  • cost 行为的诊断集(不进主混合):FVQA(MMSearch-R1) train 4,856,自带「需要搜索 / 不需要」标签,用来检查 router 是否学会简单题不检索、不调大模型;Apache-2.0,verl 格式现成。

评测套件:9 个核心 + 2 个 stretch

#数据集(split,规模)角色考察维度指标
1MMQA dev(2,441)in-domain多跳分解、模态路由list EM / F1
2Encyclopedic-VQA test(5,750,按 templated / automatic / multi_answer / 2_hop 分层)in-domain实体识别 → KB 检索;按题型看 costEM(BEM 兜底)
3TAT-DQA test(1,662)in-domain文档 OCR + 数值分解EM + numeracy F1
4ChartQA test(2,500,human / augmented 分开报)in-domainchart 组合推理relaxed accuracy
5InfoSeek val(抽 unseen-entity 5K + unseen-question 5K)OOD 知识检索未见实体的检索泛化VQA-acc + relaxed-acc 调和平均
6OK-VQA test(5,046)OOD / easy regime审稿人默认对比;简单题能否省 costVQA acc
7M3DocVQA(MMQA dev 题 over 3,368 PDF / 41,005 页)OOD 开放域文档检索分层检索(页召回 → OCR / VLM)list EM / F1 + page recall@k
8CRAG-MM single-turn(3,874 公开)OOD agentic MM-RAGmock image-KG / web search API 的工具调用 cost;abstainTruthfulness +1 / 0 / −1(judge)
9ChartQAPro(1,948)OOD 困难 chartdashboard / 多图 / chart+段落的分解分题型 relaxed acc / EM / ANLS
S1MMSearch e2e(300)+ Dyn-VQA 202502-en(706)stretch:实时搜索与 MMSearch-R1 / OmniSearch 直接对比F1 / token F1
S2MMLongBench-Doc(1,091 题 / 135 份长 PDF)stretch:长文档 long-horizon页检索 + 证据模态路由 + abstain官方 Acc / F1
核实时发现的硬限制:MathVista 的 README 禁止用于训练;SlideVQA 的 NTT 评估许可可能禁止训练(需邮件作者);Dyn-VQA 官方图片链接全部 403(只有 xandery/DynVQA 镜像的 706 张英文题可用);CC BY-NC 的集合(CRAG-MM、MMLongBench-Doc、LiveVQA、MTA-Vision-DeepSearch、SEED-Bench;ScienceQA 为 NC-SA)只能做论文实验,不能进发布物;MMQA、E-VQA、OK-VQA 没有写明 license。长答案集(WebQA、CRAG-MM、VisDoMBench)不要用 recall 式或子串式评分当 reward(会奖励啰嗦);多选题集(A-OKVQA、ScienceQA、M3CoT,随机基线 25–50%)不进主训练混合。

关于「chat-qa」:最可能是 ChartQA(已在推荐里);另一种读法 NVIDIA ChatQA 是文本对话 QA 的模型系列,nvidia/llama3-chatqa-1.5-8b 出现在 Router-R1 代码的价格表里,不是 VQA 数据集。

最接近的先行工作(写论文时要对比):OmniSearch / Dyn-VQA(ICLR 2025,planner + 逐步检索)、MMSearch-R1 / FVQA(ACL 2026,只在答对时施加搜索惩罚)、M3DocRAG(分层页检索)、CRAG-MM(KDD Cup 2025)。

需要你拍板的 6 个问题

  1. 池子里的 API 模型(GPT-4o / ChatGPT)直接看图(最准、最贵、按图像 token 计费),还是只看本地视觉模型产出的文本证据?这决定路由协议和价格表。
  2. 知识检索训练集选 Encyclopedic-VQA(test 公开、显式 2_hop、有证据段;但 license 未写明、图像要自下)还是 InfoSeek(Apache-2.0、934K train、Wiki6M;但只有 val 有标签、294 GB gated 图像)?两者都要几百 GB 图像,由存储预算定。
  3. 训练用闭域设定(MMQA:每题 1 表 + 10 段 + ≤15 图,rollout 便宜)还是开放域(M3DocVQA 3,368 份 PDF / E-VQA 2M 篇 KB,更贴多模态 RAG 的故事,但 rollout 成本高几倍)?
  4. 评测能不能接受 LLM judge?CRAG-MM、MMSearch-Plus、BrowseComp-VL、MM-BrowseComp、LiveVQA 都用 GPT-4o / GPT-5 judge;只用规则指标的话 agentic 一族只剩 MMSearch 和 Dyn-VQA,且都依赖实时搜索。
  5. license 红线:「明确允许训练」是否作为硬过滤?那样 MMQA 和 E-VQA 会被质疑,CC BY-NC 集合不能进发布物,训练混合会偏向 InfoSeek + TAT-DQA + ChartQA(GPL-3.0 有 copyleft 顾虑)。
  6. planner 也做 RL 训练吗?是的话保留 MMQA type program / GQA program / VQA-Introspect 子问题当 process reward;planner 冻结的话这些字段只用于分析。

51 个数据集总表(按适配度排序)

分家族详述

每张卡片:年份 / 会议 / 图像来源、问题长什么样、对 planner + router 的意义与坑、核实备注。

#数据集年份 / 会议家族规模答案形式指标traintest 标签检索语料许可fit
1Encyclopedic-VQA2023 · ICCV 2023Knowledge221k unique Q+A pairs over 16.7k categories, 514k unique im…short free-form; multiple annotat…Accuracy (mean per-example score)…✓✓yes: controlled Wikipedia KB…Data/KB: not stated i…5
2MultimodalQA (MMQA)2021 · ICLR 2021Multi-hop29,918 Q: train 23,817 / dev 2,441 / test 3,660 (counted fr…short free-form: a list of answer…EM and F1 with DROP-style alignme…✓✗yes, closed per-question cont…unverified: GitHub AP…5
3CRAG-MM2025 · KDD Cup 2025 challenge benc…Multi-hopFull benchmark: 6,462 single-turn (image, question, answer)…short free-form: one full-sentenc…Truthfulness = mean per-answer sc…△△yes: mock image-KG search (68…CC BY-NC 4.0 (stated…4
4ChartQA2022 · Findings of ACL 2022 (ACL A…DocumentChartQA-H: train 3,699 charts / 7,398 Q, val 480 / 960, tes…short free-form (number or short…relaxed accuracy (following Metha…✓✓none (no retrieval corpus). T…GPL-3.04
5GQA (balanced)2019 · CVPR 2019 (oral)GeneralFull set 22M questions; total image count unverified (not s…short free-form: a single gold 'a…Accuracy: exact match against the…✓△none as a retrieval corpus. S…CC BY 4.0 (official d…4
6InfoSeek2023 · EMNLP 2023 (main conference)KnowledgeInfoSeek_Wikidata 1,355,648 Q total (1.35M), 11,481 entitie…short free-form: an entity attrib…VQA accuracy for STRING and TIME…✓△yes: Wiki6M, about 6M Wikiped…Apache-2.0 (annotatio…4
7M3DocVQA (from M3DocRAG)2024 · ICCV 2025 Workshops (CVF op…Multi-hopEval (dev): 2,441 multi-hop questions (= MultimodalQA dev)…short free-form; may be a list of…Answer: list EM / list F1 (MMQA/D…✓△yes: 3,368 rendered Wikipedia…code Apache-2.0 (LICE…4
8MTA-Vision-DeepSearch2026 · arXiv preprint 2604.06376 (…KnowledgePaper Table 1: 21,155 train (seed/1-hop 8,456 + 2-hop 4,431…short free-form entity (proper no…LLM-judge accuracy: GPT-5 check_a…✓✓none (live web text/image sea…CC BY-NC 4.0 (LICENSE…4
9TAT-DQA2022 · ACM Multimedia 2022 (MM '22…Document16,558 Q / 2,758 documents / 3,067 pages, from 182 financia…short free-form / numeric: span,…Exact Match + numeracy-focused (m…✓✓none (closed per-question con…CC BY 4.04
10WebQA2022 · CVPR 2022 (arXiv comment 'C…Multi-hoptrain 36,766 / val 4,966 / test 7,540 Q (README), equal to…long-form natural-language senten…Source retrieval F1; QA = mean of…△✗yes: per-question distractor…CC0-1.0 (repo LICENSE…4
11A-OKVQA2022 · ECCV 2022 (LNCS vol. 13668,…Knowledge24,903 questions (paper: 'about 25K'): train 17,056 / val 1…multiple-choice (4 choices, corre…MC accuracy (exact match to choic…✓✗none (the paper says the ques…Apache-2.0 (official…3
12BrowseComp-VL2025 · ICLR 2026 (WebWatcher; conf…Knowledgereleased test 399 Q / 399 images (Level 1: 199 explicit ent…short free-form, one gold string…LLM-as-judge binary correctness,…△✓none (live web text + image s…no dataset-specific l…3
13ChartQAPro2025 · Findings of ACL 2025 (Vienn…Documenttest only: 1,948 Q (HF 'test' split, 1,948 rows) over 1,341…short free-form (word / number /…enhanced relaxed accuracy per typ…△✓none (some items include an a…MIT (GitHub repo and…3
14DUDE2023 · ICCV 2023 (arXiv comments '…Document41,541 Q / 5,019 份英文多页文档(平均 5.72±6.4 页,1,831.53±2,545.06 to…short free-form:Extractive 42.39%…ANLS 为主(多参考答案);另报 ECE(以 ANLS>τ=0.…△✗每题对应一份多页 PDF,附 OCR(Amazon / A…CC BY 4.0(HF card 和 D…3
15DocVQA (Single-Page) + MP-DocVQA2021 · DocVQA: WACV 2021; MP-DocVQ…DocumentSP-DocVQA: 50,000 Q over 12,767 images from 6,071 docs; tra…short extractive span (verbatim c…ANLS (primary; ST-VQA definition;…✓✗SP: per-image OCR (line + wor…SP: RRC portal terms…3
16Dyn-VQA2024 · ICLR 2025 (poster)Knowledgetest-only, 1 image per Q. 202406/202412: 1,452 Q (715 en /…short free-form (avg answer lengt…Token F1-Recall as implemented in…△✓none (designed for live web/i…apache-2.0 (official…3
17FVQA (MMSearch-R1 Factual VQA)2025 · ACL 2026 (Long Papers, Vol.…KnowledgeHF: train 4,856 Q (search_required 3,312 / search_free 1,54…short free-form entity/fact span;…training reward: normalized EM (S…✓✓no retrieval corpus; the HF r…Apache-2.0 (HF card a…3
18InfographicVQA2022 · WACV 2022, pp. 2582-2591, D…Document30,035 Q / 5,485 infographics from 2,594 web domains. train…short free-form; Answer-source =…ANLS (tau=0.5) primary + Accuracy…✓✗none (single image per questi…QA annotations CC-BY…3
19LiveVQA2025 · NeurIPS 2025 Datasets and B…KnowledgePaper v2: 107,143 Q / 28,488 images; train 104,143 Q / 26,9…Short free-form answer (paper's m…Accuracy (%) from a SimpleQA-styl…✓✓partial: each sample's 'text'…CC-BY-NC-4.0 (ONE-Lab…3
20M3CoT2024 · ACL 2024 (Main, Long Papers…ExpertHF: train 7,863 / validation 1,108 / test 2,318 Q (11,289 t…multiple-choice, 2-5 options (mea…accuracy (official regex letter e…✓✓none (gold rationales only, n…MIT per HF card YAML…3
21MMK122025 · arXiv preprint 2503.07365 (…Experttrain 15,616 Q (math only; 455 elementary / 9,776 middle /…split-dependent: train = fill-in-…accuracy; test = MCQ option accur…✓✓noneunverified: no licens…3
22MMLongBench-Doc2024 · NeurIPS 2024 Datasets and B…DocumentCurrent release: 1,091 Q / 135 PDFs (avg 47.5 pages, 21,214…short free-form typed answer: Str…Generalized Acc and F1 (headline…△✓135 long PDFs (per-question d…data CC BY-NC 4.0; co…3
23MMMU2023 · CVPR 2024 (Oral)Expertdev 150 / validation 900 / test 10,500 Q (11,550 total, 3.6…multiple-choice (10,861 Q, 94.03%…micro-averaged accuracy (MC + ope…△✓noneApache-2.0 (HF card);…3
24MMMU-Pro2024 · ACL 2025 (Long Papers), acl…Experttest only: 1,730 unique questions in 3 configs (standard (1…multiple-choice, one letter A-J (…accuracy via a letter match on th…△✓noneApache-2.0 (HF card Y…3
25MMSearch2024 · ICLR 2025 (poster; OpenRevi…Knowledgeeval-only 300 Q (14 subfields; News + Knowledge); 171 with…short free-form (gt_answer + alte…S_e2e = F1(pred, gt); S_req = avg…✗✓partial: rerank (8 candidate…MIT3
26MMSearch-Plus2025 · ICLR 2026 (Conference track)Knowledgetest-only 311 tasks (94 Easy / 217 Difficult; 279 unique qu…short free-form, avg 3.7 words (m…end-to-end accuracy (%) via GPT-4…✗✓none (live web browsing via S…CC-BY-4.0 dataset (HF…3
27MMStar2024 · NeurIPS 2024 (Advances in N…General1,500 Q / 1,500 images, one 'val' split only, no train spli…multiple-choice; gold is a single…Accuracy (overall + per core capa…△✓noneunverified: no licens…3
28OK-VQA2019 · CVPR 2019Knowledge14,055 Q on 14,031 COCO images: train 9,009 Q (COCO train20…short free-form (open-ended, mean…VQA accuracy min(#matches/3,1) ov…✓✓none official; M2KR (PreFLMR)…unverified: no licens…3
29ScienceQA2022 · NeurIPS 2022Experttrain 12,726 / val 4,241 / test 4,241 Q (21,208 total); ima…multiple-choice, 2-5 options, ans…accuracy (tools/evaluate_acc.py),…✓✓partial: each question's lect…data CC BY-NC-SA 4.0…3
30ScreenQA (+ ScreenQA Short, ComplexQA)2022 · NAACL 2025 (main, long; 202…Text-richScreenQA: ~86K QA over ~35K RICO screenshots: train 68,951…original: full_answer sentence +…SQA-S: EM + token F1 after SQuAD…✓✓none (no external corpus); ui…CC BY 4.03
31SlideVQA2023 · AAAI 2023Multi-hop14,484 QA over 2,619 decks / 52,480 slide images (20 per de…short free-form string answers, t…QA EM/F1 (HotpotQA-style, with Sl…?✓per-question deck of 20 slide…NTT 'Software License…3
32Text-KVQA (knowledge-enabled text VQA)2019 · ICCV 2019 (DOI 10.1109/ICCV…Text-richTotal 257,380 images / 1,322,272 QA (counted from official…short free-form, one gold string…VQA accuracy (%), single-answer e…✓✓yes: KB-business (500 entitie…unverified: no licens…3
33TextVQA2019 · CVPR 2019Text-rich45,336 Q on 28,408 images: train 34,602 Q / 21,953 images;…short free-form, 10 human answers…VQA accuracy (Goyal et al.): min(…✓✗noneCC BY 4.0 for the ann…3
34ViQuAE2022 · SIGIR 2022 (45th ACM SIGIR,…Knowledge3,697 Q (1 image each): train 1,190 / val 1,250 / test 1,25…short free-form (TriviaQA-derived…RC: Exact Match + bag-of-words F1…✓✓yes: viquae_wikipedia KB, 1.5…dataset CC-BY-4.0; KB…3
35WebSRC2021 · EMNLP 2021 (main conference…Text-richtrain 307,315 QA / 4,549 pages (50 websites); dev 52,826 QA…extractive span or yes/noEM, F1 (SQuAD-style), Path Overla…✓✗none (no external KB); each p…CC BY 4.0 per HF card…3
36CLEVR (incl. CLEVR-CoGenT)2017 · CVPR 2017GeneralCLEVR: train 699,989 Q / 70k images; val 149,991 Q / 15k; t…short free-form from a closed voc…Accuracy (exact match)✓△none. Ships scene graphs plus…CC BY 4.0 (CLEVR/CoGe…2
37EMMA2025 · ICML 2025 (Oral; first anno…Experttest only (no train/val): 2788 Q = Chemistry 1176 + Math 89…mixed: multiple-choice letter (20…accuracy (overall / per subject /…△✓noneunverified: no licens…2
38KVQA2019 · AAAI 2019 (Proc. AAAI vol.…Knowledge~183K QA pairs, >18K named entities (persons), 24,602 image…short free-form open-ended (avg 1…accuracy (mean over the 5 test sp…✓✓yes: Wikidata KG (2018-05-05…unverified: no licens…2
39MATH-Vision2024 · NeurIPS 2024 Datasets and B…Experttest 3,040 Q / testmini 304 Q (subset of test, sampling met…mixed: multiple-choice (A-E, `opt…accuracy (overall, per-subject, p…△✓noneMIT (HF card and GitH…2
40MM-BrowseComp2025 · EMNLP 2026 (per arXiv v2 Co…Knowledgeeval-only, no train split. v1: 224 Q (HF, single split labe…short free-form (decrypted locall…LLM judge GPT-4o-2024-11-20 (Gemi…△✓none (live web browsing; sour…MIT (HF card + GitHub…2
41MMBench2024 · ECCV 2024 (Oral); arXiv 230…GeneralOfficial: Dev 1,164 Q EN + 1,164 CN; Test 1,784 Q EN + 1,78…multiple-choice, 2-4 options (A-D…Accuracy under CircularEval: an N…△?noneApache-2.0 (GitHub re…2
42MMCoQA (MMConvQA)2022 · ACL 2022 (long, pp. 4220-42…Multi-hoptrain 4,582 Q / 943 dialogs; dev 581 Q / 118 dialogs; test…short free-form (avg 2.11 words,…word-level macro F1 + EM (SQuAD-s…✓✓yes: open collection of 218,2…unverified: no licens…2
43MathVista2023 · ICLR 2024 (Oral)Experttestmini 1,000 Q / test 5,141 Q (6,141 total, about one ima…mixed: multi_choice (choose an op…accuracy; the official pipeline f…△✗noneCC BY-SA 4.0 for new…2
44OCR-VQA2019 · ICDAR 2019Text-richPaper: 207,572 images / 1,002,146 QA (avg 4.83 Q/image); im…short free-form (title / author /…accuracy (paper does not specify…✓✓none (HF mirror includes per-…unverified: not state…2
45OCRBench v2 (and OCRBench v1)2024 · v2: NeurIPS 2025 Datasets &…Text-richv2: 10,000 human-verified QA in a single HF 'test' split (9…mixed: short strings (a list of 1…Per-task scorers in OCRBench_v2/e…△✓noneMIT (repo and HF ling…2
46SEED-Bench (v1; family incl. SEED-Bench-2, SEED-Bench-2-Plus, SEED-Bench-H)2023 · SEED-Bench-1:arXiv 技术报告 230…GeneralSEED-Bench-1:论文是 19,242 题。官方 JSON(2023-11-30 人工筛查视频题后)是 17,…multiple-choice(4 选项 A-D,单一正确答案;官…Accuracy(分维度和平均)。原论文用 likelihood-…?✓none代码 Apache-2.0。AILab-C…2
47ST-VQA2019 · ICCV 2019 (dataset paper, a…Text-rich23,038 images / 31,791 QA total; train 19,027 img / 26,308…short free-form text (extractive…ANLS (tau = 0.5; case-insensitive…✓✗noneunverified: not state…2
48VQA v22017 · CVPR 2017 (DOI 10.1109/CVPR…Generaltrain 443,757 Q / 82,783 images / 4,437,570 answers; val 21…short free-form (10 crowd-sourced…VQA accuracy: Acc(ans) = min(#hum…✓✗noneAnnotations: CC BY 4.…2
49VQA-Introspect2020 · CVPR 2020 (oral)Generalv1.0: train 166,927 sub-Q / 55,799 Reasoning Q (VQAv2 train…short free-form, mostly yes/no: m…VQA accuracy (Overall / Reasoning…✓✗noneO-UDA-1.0 (Microsoft…2
50VisDoMBench (VisDoM)2025 · NAACL 2025 Long Papers (acl…Multi-hopeval only, 2,271 Q over 1,277 docs (Q/docs): PaperTab 377/2…Mostly long-form free text: media…QA: SQuAD-normalized word-overlap…?✓yes: per-query pool of about…No LICENSE file in th…2
51VizWiz-VQA2018 · CVPR 2018 (DOI 10.1109/CVPR…Generaltrain 20,523 Q / val 4,319 Q / test 8,000 Q (current versio…short free-form (10 crowd answers…Task 1: VQA soft accuracy. Normal…✓✓noneCC BY 4.0 (official p…2

train 列:✓ 有可用于 RL 的公开训练集且答案可规则判分;△ 只有验证集或答案偏长;✗ 无。test 标签列:✓ 公开 / ✗ 只能提交 leaderboard / △ 只有验证集公开。⚠ = 核实置信度不足 0.6。fit = 对「planner + cost-aware router」项目的适配度 1–5(由核实 agent 独立评估)。

知识密集 / 实体型 VQA

2023 · ICCV 2023 · iNaturalist 2021 + Google Landmarks Dataset v2 (p…

encyclopedic questions about detailed properties of fine-grained species/landmarks ('How big can this plant become?'); 15k templated + 158k automatically generated single-hop, 25k multi-answer, 22k two-hop chained via b…

与 planner+router 设定很契合的 entity-centric 数据集:2_hop 由 bridge entity 构造,天然能拆成 A→B 证据链;single-hop 本身也是「识别实体(小视觉模型/检索)→ 查 KB section → 读答案」的链条,适合测 router 对不同子步骤选不同粒度的模型。注意约 78% 是 single-hop,显式组合题只有 2_hop(约 10%)和 multi_answer(约 11%)。可按 question_type 分层,检验 router 是否给简单题用小模型、给 two-hop 调大模型。KB 带 evidence section 标注,能单独评估 retrieval 子步骤(paper Tab. 6:Lens 取对 article 的比例是 47.4%;section 取对时 PaLM 82.3%,取错时 20.7%)。训练规模足够做 RL(train 2…

核实备注:data/KB license not stated in official README; google/encyclopedic-vqa HF repo returns 401 (nonexistent or private)

2023 · EMNLP 2023 (main conference) · OVEN (Open-domain Visual Entity Recognition): ima…

information-seeking questions about a property of a fine-grained visual entity that common sense cannot answer. Examples from the official files: 'Which place is this animal endemic to?', 'How many spans does this bridg…

适合当主训练集之一,尤其适合 cost-aware router 和 RL reward。问题天然是两步证据链:(A) 视觉实体识别(小而快的视觉模型 / CLIP 检索即可)→ (B) 在 KB 中查属性(text LLM + retrieval)。这正好对应 planner 拆成 A、B,router 再给 A、B 选不同粒度的模型。paper 中 PaLI-X fine-tuned 只有 22.1 (Wikidata) / 10.8 (Human),CLIP→FiD 19.3 / 18.2,Oracle entity→FiD 52.0 / 45.6,说明 entity recognition + retrieval 是瓶颈,模型选择有很大空间。934,048 train 足够做 RL 采样,reward 可直接用官方 rule-based 指标(VQA-acc + relaxed-acc)。KB 现成:repo 发布了…

核实备注:per-source image licenses (OVEN); M2KR Infoseek split breakdown / answers; MMSearch-R1's claimed 'test split' sampling

2026 · arXiv preprint 2604.06376 (v1 2026-04-0… · seed VQA images: FVQA, InfoSeek (OVEN/Wikipedia e…

multi-hop (1-5 hop in released qids; paper 2-4 hop + seeds) visual deep-search questions built by chaining entities from a seed VQA image (e.g. infographic → company → city → rail line); the answer requires web/image se…

多模态 deep-search 训练集里少有的开源、上千量级、显式按 hop 构造的数据。qid 自带 _Nhop,hop 链天然就是 planner 要输出的 evidence chain(A→B→C)。它混合了 InfoVQA(OCR/infographic)和 InfoSeek/OK-VQA/FVQA(实体知识),router 可以在 OCR 小模型 / VLM / 文本 LLM / search 之间按子问题选择,hop 数又能直接当 cost-aware curriculum 的难度标签。风险:(1) 2026 预印本,没有同行评审;(2) CC BY-NC 4.0 加 OpenAI 非竞争条款,只能做学术用途;(3) HF 实际训练文件只有 7,110 行,与论文的 21,155 对不上,README 里的 livevqa_news 训练子集也不存在,下载后要自己统计;(4) reward 依赖 GPT-5 jud…

核实备注:HF train files (7,110 rows) are smaller than the paper's 21,155; livevqa_news_qw3vl training subset listed in README does not exist on HF; LICENSE says data generated with GPT-4.1 while the paper names GPT-5 family models

A-OKVQAfit 3
2022 · ECCV 2022 (LNCS vol. 13668, pp. 146-162… · COCO 2017 (train2017/val2017/test2017)

crowdsourced short questions needing commonsense + world knowledge + visual reasoning, each with 3 natural-language rationales

有 17K train,标签干净,MC 和 DA 的 reward 都能直接按规则算(官方 DA 指标就是 min(1, 匹配数/3)),很适合 GRPO。每题配 3 条 rationale,可以拿来弱监督 planner 的分解(rationale≈证据链)。缺点有三:知识以 commonsense 为主;问题短,多为单跳;也不附 KB 或检索语料。真正需要外部检索或多步拆分的题不多,router 在这里多半会学到「大部分题小 VLM 就够」。所以更适合当 cost-saving 的 easy-regime 混合训练数据和 sanity check,撑不起主打的复杂度。test 标签不公开,只能用 1,145 道 val 评测(量偏小),或者提交 leaderboard。另外 HF 镜像里的 direct_answers 是字符串化的 list,需要先 parse;做 DA 评测时要按官方脚本剔除 difficult_dir…

核实备注:share of difficult_direct_answer questions not counted

2025 · ICLR 2026 (WebWatcher; confirmed on pro… · web / Wikipedia-derived images, shipped as tar ar…

BrowseComp-style multi-hop deep research starting from an image; Level 1 names the entity explicitly; Level 2 blurs entities over Wikipedia hyperlink chains, so questions are long and riddle-like; covers 10+ domains (Mu…

Level 2 的实体模糊化 + 多跳检索,与我们 evidence-chain planner 的分解思路高度契合,而且是同领域常用的对比 benchmark。数据已在 GitHub 公开:399 题带 gold answers,图片为 tar 包,可以直接下载做 held-out eval。不足有三点:没有训练集(论文中的 10 万条训练 QA 未发布),L2 答案偏长、官方用 LLM judge,依赖 live web search,成本高且结果难复现。建议把它作为 long-horizon agentic 的 eval benchmark,RL 训练改用其他带 train split 的数据。另外报告结果时要注明用的是 released 399 题,还是论文附录里 300 题的子集。

核实备注:judge model not named in the main text; released 399 vs paper appendix 300 eval subset

Dyn-VQAfit 3
2024 · ICLR 2025 (poster) · Annotators found images via Google, excluding Wik…

dynamic questions needing adaptive retrieval: rapidly changing answers, questions that need multimodal knowledge (visual entity recognition + web), multi-hop questions; zh and en parallel

复杂度最贴近我们的 idea:OmniSearch 本身就是『planner 把复杂多模态问题拆成 sub-question chain,每步配 retrieval action』,可作为直接对比的 agentic baseline。paper Table 4:OmniSearch(GPT-4V) 44.04 vs GPT-4V 无检索 17.63;GPT-4V 底座最好 heuristic mRAG 24.90,全表最好 heuristic 26.71 (Qwen-VL-Max);human 51.63。26.7% 题需要 >2 hops,适合检验 evidence-graph planner;golden_query 字段可当 decomposition 第一步(实体消解)的 oracle。主要风险:(1) 官方图片 OSS 链接已全部 403(issue #15),只能用第三方 xandery/DynVQA 的 en 2…

核实备注:image copyright not addressed; official OSS image URLs return 403 (dead) as of 2026-10-31; only the xandery/DynVQA en-202502 mirror has images

2025 · ACL 2026 (Long Papers, Vol.1, pp. 2456–… · FVQA-auto-vc: web/Google image search over sample…

fact-seeking, knowledge-intensive visual questions about the entity in the image (e.g. 'What country does this building belong to?'), mostly single-hop; train balanced between search-required and search-free

这是和我们 cost-aware reward 最直接的先例:MMSearch-R1 的 reward = 0.9·Acc·SearchPenalty + 0.1·Format,答对但调用过 search 时 Acc 乘 (1-0.1)=0.9(代码 compute_score;可选 use_search_count_penalty 按次数累乘),答错不罚,以此学 on-demand search(abstract:比同规模 RAG 好,且 search 调用减少 >30%)。本质是 Router-R1 式 performance-cost trade-off 在多模态检索上的单工具/二元版本,可直接借鉴其 'penalty 只作用于正确样本' 的设计。train 有 search_required/search_free 标签(3,312/1,544),可检验 router 是否学会『简单题不调大模型/不检索』;test 没…

核实备注:whether the InfoSeek-derived subset inherits InfoSeek's own license terms

LiveVQAfit 3
2025 · NeurIPS 2025 Datasets and Benchmarks Tr… · Recent news article images (CNN, BBC, AP, Forbes,…

Live / recent visual knowledge. Level 1: identify the entity, event, location or person in a recent image. Level 2: cross-modal multi-hop questions about that entity's recent facts (time, count, reason, etc.), drawn fro…

规模大(约 10.4 万题可作训练池),且 level 1/2 天然对应“先用 VLM 识别图中实体 → 再用 text search / LLM 查新知识”的两步证据链,适合 planner 拆题、cost-aware router 学习“L1 只调小 VLM、L2 才调 search + 大模型”。注意几点:(1) 论文主评测是 open-ended + LLM judge,不是 MC;如果用 MC letter 做 reward,答案字母严重偏斜(B 占 41%),必须 shuffle options。(2) 官方公开的 test(fmy666/livevqa-benchmark,2,384 题)与论文所说的 3,000 题不一致,而且有 1,339 题与 HF 的 LiveVQA-new 'train' 重复,自建 split 前必须去重。(3) 知识集中在 2024-04 至 2025-05,模型 knowledge…

核实备注:names of the 12 categories (paper never lists them); how the 327% average improvement was computed; paper Table 1 internal inconsistencies (arXiv row totals)

2024 · ICLR 2025 (poster; OpenReview J2Jyp1SZ0… · annotator-curated query images; Google Lens image…

multimodal search-engine queries: recent news (2024-05-01 to 2024-08-31) and rare knowledge (architecture, arts, fashion, astronomy, anime, auto ...); stepwise requery -> rerank -> summarize, plus end-to-end

多模态搜索 agent 的标准 OOD 评测。MMSearch-R1、WebWatcher 等后续工作都在它上面报告结果,作对比基线几乎必选。F1 指标可直接复用。局限:只有 300 条,没有 train split(HF 上 3 个 config 各 300 行,split 名就是 config 名)。end2end 要接实时 Google Lens + 搜索引擎,结果不可复现,建议固定 search cache。rerank/summarization 子集带固定网页快照,可以离线评测检索后的 aggregator 环节。新闻数据集中在 2024 年 5-8 月,已在新模型 knowledge cutoff 之内,需注意数据污染。requery/rerank/summarize 三个分步子任务可分别对应我们 pipeline 的 planner(子问题改写)、router/检索和 aggregator,用于细粒度分析。

核实备注:paper counts 163 query images vs 171 image-bearing questions (gap unexplained); project page dataset-download link points to the MathVerse HF page (site bug)

2025 · ICLR 2026 (Conference track) · web images, arXiv papers, video frames (arxiv_id…

BrowseComp-style hard browsing: fine-grained visual cues, provenance tracking, multi-step iterative image+text search; categories geography, sports, academia, film/TV, technology, games, vlogs, music

高难度 long-horizon 多模态 browsing 评测(ICLR 2026),需要细粒度视觉线索 + 多轮 image/text search + provenance 追踪,与 planner(证据链分解)+ 迭代检索 + cost budget 的设定高度契合,可报告“给定 cost 下的 accuracy”曲线。缺点:只有 311 条且无训练集;gold 需用 canary 解密;依赖实时 SerpApi 搜索(付费、结果随时间漂移),官方 rollout/eval 代码尚未发布;开源 72B 模型 full rollout 只有 6.1,7B 级 router 的结果可能全部贴地。建议作为 stretch / out-of-domain 评测,不做主表或训练数据。

核实备注:'up to 5 images' comes only from the HF schema (img_1..img_5); official agentic rollout/eval code still a ToDo

OK-VQAfit 3
2019 · CVPR 2019 · MS-COCO 2014 (train2014 / val2014)

questions the image alone cannot answer, needing outside (commonsense / encyclopedic) knowledge; 10 knowledge categories plus 'Other' (Vehicles and Transportation; Brands, Companies and Products; Objects, Material and C…

经典 KB-VQA 基准,审稿人默认会要求对比,必须报。有 9,009 train split,test 标签全公开,指标 rule-based(VQA acc + Porter stemming),适合直接做 GRPO reward。M2KR 的 OKVQA_passages(114,809 条 passage)可直接用作 retrieval corpus。缺点:问题短(1.3 词答案),多为单跳;每题只有 5 个人工答案(复制成 10 个),答案噪声较大;现代 VLM 已接近饱和,所以 planner 拆分和 cost-aware router 的收益空间小。适合作为 easy regime:验证 router 能否把简单题路由到小模型或纯 VLM、不调用检索,从而省 cost。不宜作为体现 planner 价值的主集。注意 test 实际就是 COCO val2014,没有独立 val,调参需从 train 切出 hel…

核实备注:no license stated on official site or HF cards; source of the M2KR OKVQA passage corpus

ViQuAEfit 3
2022 · SIGIR 2022 (45th ACM SIGIR, pp. 3108-31… · Wikimedia Commons (question images in PaulLerner/…

TriviaQA questions where the named entity is replaced by a referring expression ('Who did he shoot in November 1963?'); the entity (person / landmark / product etc.) is shown only in the image

结构是固定的两步链:『VLM/人脸/实体识别 → 查 KB 属性 → reader 抽答案』,对 planner 来说可拆成 A(识别图中实体)→ B(检索 + 阅读)两个子问题,router 可在 A 上选小视觉模型或人脸模型、在 B 上选文本 LM,cost trade-off 清晰。KB(1.5M 带图 Wikipedia + 12M passages)和检索代码现成,所有 split 标签公开,license 宽松(数据 CC-BY-4.0,KB CC-BY-3.0)。不足:只有 3.7K 题、train 仅 1,190,不够做 RL 主训练,适合作为 InfoSeek 类任务的小规模 OOD 评测;分解深度固定为两步、并行结构少;答案别名来自 TriviaQA 远程监督,EM reward 有噪声;人物题依赖人脸识别,涉及隐私考虑。SIGIR'22 原文表格因 HAL/ACM bot 保护未能直接核对。

核实备注:SIGIR'22 baseline numbers (EM 18.06/22.07, oracle 57.55) only from a third-party summary; HAL/ACM PDF blocked by bot protection

KVQAfit 2
2019 · AAAI 2019 (Proc. AAAI vol. 33, pp. 8876… · Wikipedia images of persons (dataset images 25 GB…

10 non-exclusive categories (spatial, 1-hop, multi-hop, Boolean, intersection, subtraction, comparison, counting, multi-entity, multi-relation) about named persons in the image, answered through the Wikidata KG

multi-hop、intersection、comparison 这类题配上 Wikidata KG,天然适合 planner 拆证据链(先识别人脸/实体,再查关系,再做下一跳),也能检验 router 是否把小模型(face/entity linker)和 LLM 分开调度;train 集大、答案短,可直接用 EM 做 reward。缺点:只覆盖人物,强依赖人脸识别,有隐私和伦理风险,ICML 审稿可能质疑;2019 年的模板化问题;作者没写 license;全量下载要 86GB+。M2KR 的 KVQA 只是检索任务,没有 QA gold。建议在 related work 或附录里作为 KG multi-hop 的补充,不进主实验。

核实备注:no license stated by the authors; paper Table 4 best numbers (closed-world ~59.2 / open-world ~36.8, MemNet) not confirmed cell by cell

2025 · EMNLP 2026 (per arXiv v2 Comments, auth… · input images in the dataset plus live web pages,…

BrowseComp-style hard multi-hop browsing questions; key evidence sits in images/videos on web pages (some questions carry an input image); each question has a hand-verified checklist (the minimal reasoning path). v2 che…

每题都有人工核验的 checklist(最小推理路径,共 1,237 条),可以直接用来评估我们 planner 拆出的子问题 / evidence graph 是否覆盖了必要证据,这是它独有的价值。缺点:只有 400 题(HF 上仍是旧版 224 题),没有 train split;证据依赖实时网页和视频(v2 中视频占 15.6%);最强的 GPT-5-High 也只有 OA 24.25,开源 agent 都低于 10%;数据加密发布且有防污染要求。所以不适合做 router 的 RL 训练集,也不适合当主评测。建议定位为 long-horizon / agentic 的 hard 辅助评测,外加 planner 质量分析集;需要视频和实时浏览工具,cost 会很高。注意报告时注明用的是 224 还是 400 版本。

核实备注:EMNLP 2026 venue is author-reported on arXiv v2, not confirmed in the ACL Anthology

多跳 / 组合式多模态 QA

2021 · ICLR 2021 · Wikipedia (in-table images and WikiEntity images)

Compositional multi-hop. Single-modality questions (TextQ / TableQ / ImageQ / ImageListQ) are combined with Compose / Compare / Intersect into 16 types, then rephrased by crowdworkers. Each train/dev question keeps its…

本 family 里最贴近我们 idea 的数据集,相当于多模态版 HotpotQA。(1) 每道 train/dev 题都带 compositional type program(16 类,如 Compare(Compose(TableQ,ImageQ),TableQ))和 pseudo_language_question,相当于自带 evidence-dependency chain 的 gold 结构,可以监督或评估 planner;intermediate_answers 只覆盖 44.3% train,dense reward 只能用在这部分题上。(2) 子问题天然按模态拆开:TextQ 交给 text LLM,TableQ 交给 table/text LLM,ImageQ/ImageListQ 交给 VLM 或小 vision model;每个 answer 也标了 modality,router 选 model…

核实备注:license (GitHub API license null, no LICENSE file); HF mirrors are unofficial (provenance unverified)

CRAG-MMfit 4
2025 · KDD Cup 2025 challenge benchmark (Meta)… · egocentric photos taken with Ray-Ban Meta smart g…

Factual questions about the image, mostly about one visual entity. Single-turn categories: simple-knowledge 40.4% (2,614), comparison 15.1% (977), multi-hop 14.4% (928), aggregation 12.0% (772), reasoning 11.0% (709), s…

2025 年最新的多模态 RAG benchmark(Meta,KDD Cup 2025)。最大卖点是自带可离线复现的 mock image-KG search 和 web search API,HF 上有 image-search-index / web-search-index 的 validation 与 public-test 版本,因此我们的 router 可以在“小 vision model 识别实体 → image search → web search → LLM 聚合”之间做带 cost 的调度。query_category 标签给出 comparison 15.1%、multi-hop 14.4%、aggregation 12.0%、reasoning 11.0% 这类可分解题型(合计约 52%),适合 planner 拆子问题。missing=0、incorrect=-1 的打分和我们“cost 到上限还…

核实备注:no peer-reviewed venue found (arXiv preprint; HF citation is a placeholder)

2024 · ICCV 2025 Workshops (CVF open access, I… · Wikipedia articles rendered to PDF with Playwrigh…

The same compositional multi-hop questions as MultimodalQA, but the evidence has to be retrieved from a pool of 3k+ multi-page PDFs (page images) instead of a given context

这是 MultimodalQA 的“视觉文档 + open-domain retrieval”版本(ICCV 2025 Workshops 已正式发表),正好对应我们“分层检索 + 选合适粒度的 model”的设定:先用便宜的 page retriever(ColPali 一类)召回页面,再决定调用 OCR 小模型、text LM 还是大 VLM,不同选择的 cost 差异很大。题目和 decomposition 完全继承 MultimodalQA(question type、modality 标签都在),train 可以用 MMQA train 加对应的 24,162 个 PDF。论文 baseline 偏低,有提升空间:M3DocRAG(ColPali + Qwen2-VL 7B)overall EM/F1 为 31.4/36.5(4 pages),text RAG 为 17.8/23.7。官方 evaluate.py(l…

核实备注:number of training questions (MMQA train usually cited as 23,817, not re-checked); ad6398/m3docvqa is an unvetted third-party mirror

WebQAfit 4
2022 · CVPR 2022 (arXiv comment 'CVPR Camera r… · web-crawled images with captions, mainly from Wik…

Open-domain multi-hop: first select the sources (on average 1.4 images or 2.0 text snippets), then answer in a full sentence. Image-based test questions split into Y/N 935, MC 981, Color 228, Shape 62, Number 200, Other…

优点:规模大(train 36,766),有真正的 image+text 检索池(每题约 15-16 个 text distractor 和 12-16 个 image distractor,另有约 390K images / 540K snippets 的 full-pool 设定),license 是 CC0(但原始图文版权仍归 Wikimedia 等来源站点)。数据里同时有 image-based 和 text-based 两类题,router 要学会判断用图还是用文本:text-based 题根本不需要调用 vision model,cost-aware routing 在 vision model、VLM 和 text LLM 之间有明确的取舍空间。不足:(1) 多数题只是“1-2 个 source 合起来答”(平均 1.4 张图或 2.0 段文本),显式子问题依赖链不如 MultimodalQA 清晰,planne…

核实备注:CVPR proceedings page not opened directly (venue from arXiv comment); TreezzZ/WebQA mirror contents not inspected

2023 · AAAI 2023 · SlideShare slide decks (original image URLs partl…

Single-hop 12,466 (86%) / multi-hop 2,018 (14%) overall; 49.3% need multi-hop or numerical reasoning; 25.5% of numerical questions need arithmetic. Test is harder: 25.6% multi-hop (Single-Hop 1124 / Single-Hop & Discret…

结构上很合适:train 有 10,617 题(1,919 decks),需要先从 20 张 slide 里选 evidence slide,再做 OCR 或 VLM 读取,最后算数,正好对应 planner、retrieval、router 三步。OCR-heavy,能体现“小 OCR model 与大 VLM”之间的 cost trade-off。evidence_pages 和 arithmetic_expression 可以直接做 rule-based 的中间 reward。test labels 已公开(GitHub test.jsonl 带 answer 和 evidence),可以本地评测,不依赖 leaderboard。test 的 multi-hop 占比 25.6%,比全集的 14% 高,适合当困难评测集。主要风险是 license:NTT evaluation license 第 1 条只允许内部“tes…

核实备注:whether NTT grants written permission for training use (needs an email to the authors)

2022 · ACL 2022 (long, pp. 4220-4231) · Wikipedia (via MultimodalQA)

multi-turn conversational questions with coreference and ellipsis, made by splitting MultimodalQA complex questions; the modality can change from turn to turn (57.7% of dialogs use 2 modalities, 24.4% use 3); each turn…

它是把 MultimodalQA 的复杂题拆成逐轮单跳子问题再改写成对话。每轮都标了 gold_question(去上下文的自包含问题)、question_type(text/table/image)和 evidence(qrels),所以可以拿来给 planner 拆题做辅助监督或分析,比如检查 router 有没有按子问题的模态选对 model。数据文件里只有逐轮子问题,没有原始的复杂母题,要恢复母题得回连 MultimodalQA(未验证可行性)。缺点:规模小(train 4,582);对话设定和我们的单问题 planner 不一致;license 没写;open-retrieval baseline 极低(F1 不到 5),给了 evidence 后 F1 能到 28 左右,说明瓶颈主要在 retrieval。图像来自 Wikipedia,不需要 OCR。建议不做主数据集,只当 decomposition 和模态路由的…

核实备注:license (neither repo nor upstream MultimodalQA states one); recovering the parent complex MMQA question by joining back was not verified

2025 · NAACL 2025 Long Papers (aclanthology 20… · PDFs of arXiv CS/ML papers (PaperTab via QASPER/U…

Multi-document QA: find the right document among about 8 candidates, then answer from a table, chart, figure or slide (often explanatory 'why/how' questions for SciGraphQA and SPIQA). Some questions were rewritten by GP…

优点:覆盖 table / chart / slide 三种视觉元素,每题都要先在约 8 个候选 PDF 里 retrieve 出正确文档,可以测 router 的 document identification 和 modality 选择(text-only RAG 还是 VLM,是否需要 OCR)。另外有 evidence / evidence_pages 标注,可以检查中间证据。缺点:只有 2,271 题且没有 train split;约 75% 的 gold 是长句(SciGraphQA 中位数 57 词),word-F1 reward 噪声大、偏向长回答;大多数题是“找对文档再回答”,没有显式的证据链可以分解(只有 SlideVQA 子集有 multi-hop + arithmetic);官方 eval.py 只算 word F1,retrieval 指标要自己实现;license 混合了 CC-BY-SA、MIT…

核实备注:SlideVQA 'evaluation-only' license wording not re-opened in this pass; no LICENSE file in the repo

文档 / 图表 / 信息图 VQA

ChartQAfit 4
2022 · Findings of ACL 2022 (ACL Anthology 202… · real charts crawled from Statista, Pew Research,…

H: AMT human-written compositional / visual / data-retrieval questions (Table 4 shares above). M: generated by fine-tuned T5 from Statista human-written chart summaries, test set manually cleaned. Chart types: bar, line…

图表 VQA 的标准基线。ChartQA-H 的 300 题抽样里 compositional 43.0%、visual+compositional 33.3%、visual 10.7%、data retrieval 13.0%(Table 4),多数题天然可以拆成 '读 series X / 读 Y → 比较或算术' 的子问题链,很适合 planner。完整 release 里除 Pew 以外的图表都附 CSV data table 和 SVG 衍生的 bbox 注释(Pew 是人工标注,注释有噪声),所以可以设计 '小模型 chart-to-table + text LLM 推理' 与 '大 VLM 直接答' 两条 cost 不同的路径,让 router 学 trade-off。relaxed accuracy 是纯规则,可以直接做 reward;train 28,299 条,test 标签公开。缺点:只有 bar/lin…

核实备注:whether the release adds CSV tables for the Pew charts (HF repo files not listed)

TAT-DQAfit 4
2022 · ACM Multimedia 2022 (MM '22, Lisboa) · real-world financial annual reports (annualreport…

questions written by finance experts (reusing TAT-QA's plus new ones) that need discrete reasoning over tables + text in financial reports: extraction, addition / subtraction / multiplication / division, counting, compa…

表格+文本混合的真实财报页图,约 42% 是 Arithmetic(6,958/16,558),问题天然能拆成「定位单元格/文本 A、定位 B → 计算」这样的证据链,适合测 planner 的分解。子问题之间差异明显:版面/表格定位交给 OCR 或小 VLM,纯算术交给 text LLM 或 code 工具,有不少 Span 问题小模型就能答,所以 cost-aware router 能省下来的空间比较实在。答案短,有 scale,官方 tatqa_eval.py 可以直接当 rule-based reward;train 有 13k,够做 GRPO;test gold 已公开(HF 上有 test_gold.json),能离线评测。局限:只有财报这一个领域;大部分文档是单页(train 2,004/2,207),平均 1.33 页/文档,几乎没有跨页检索压力,作为 '多模态 RAG' benchmark 偏弱,更适合放在「…

核实备注:HF account next-tat not self-declared as official (inferred from TAT@NExT label and links)

2025 · Findings of ACL 2025 (Vienna), pp. 1912… · real charts from 157 online sources (74% web-craw…

human-written, human-verified (LLM-assisted generation followed by manual filtering and revision): factoid / math & visual reasoning, MCQ, multi-turn conversational, hypothetical, fact-checking, unanswerable, multi-char…

ChartQA 的高难度升级版,覆盖 multi-chart / dashboard / infographic、conversational、hypothetical、unanswerable,还有一部分题附带 Paragraph 文本,需要把图和文结合起来推理。模型和人类差距大(55.81 vs 85.02),适合作为“复杂 chart 题”的 held-out 评测,用来看 planner 分解加 cost-aware router 在难题上有没有增益。dashboard / 多图和 chart+paragraph 这两类题天然可以拆成子问题(先定位子图或读文本,再计算),所以和 planner 比较对口。短板:只有 test split(1,948 题),不能当 RL 训练数据,需要配 ChartQA 或其他 chart 训练集来训、在这里评测;规模小,按题型细分后方差大。评测规则都能写成程序(RA / EM / AN…

核实备注:count of unanswerable questions (paper gives none); official evaluate_predictions.py does not enforce EM for MCQ/fact-check (bug)

DUDEfit 3
2023 · ICCV 2023 (arXiv comments 'Accepted at… · 手工从 archive.org、commons.wikimedia.org、documentclo…

由 MTurk 标注者和 5 名 PhD 语言学家编写的文档问题,包括 multi-hop、meta/layout-navigating(如 'which page contains the largest table')、arithmetic/comparison/counting、list、non-answerable

多页、多领域(1860-2022,born-digital + scan),题型包括 multi-hop、meta/layout-navigating、arithmetic/comparison/counting、list 和 unanswerable,比 DocVQA 难得多;平均约 5.7 页,需要跨页定位证据(文档内检索,不需要外部 KB)。12.74% 的 None 答案加上 ECE/AURC 评测,正好对应我们 'cost 到预算还 hard to answer 就停止' 的设计,可以把 abstain 当作一个有奖励的动作。train 有 23.7k Q,CC BY 4.0。对 planner 有用的是:train/val 每题都有 answer_type 和 answers_page_bounding_boxes(含 page),可以当作证据页/路由的弱监督。扣分点:(1) test GT 不公开(loader…

核实备注:how list answers are scored in the official evaluator; whether test GT was released after 2023 (no evidence found)

2021 · DocVQA: WACV 2021; MP-DocVQA: Pattern R… · UCSF Industry Documents Library scans (letters, m…

crowd-written extractive questions on industry document scans, mostly single-hop and single-page (MP-DocVQA: the same questions posed over the surrounding multi-page document; needs_retrieval applies only to MP page sel…

用户点名的 DocVQA。SP-DocVQA 题目基本是单页、抽取式、单跳;MP-DocVQA 的问题直接沿用 SingleDocVQA,作者明确写到强制跨页标注'very unnatural',所以本身几乎不需要 planner 分解。它的价值在于规模大、答案是短 span、ANLS/EM 规则可算,适合作为 cost-aware router 的 'easy tier':训练 router 对简单题只调用小 OCR 或小 VLM,体现 cost 节省。MP-DocVQA 有 1-20 页上下文和 answer_page_idx 标注,可以练 '先选页再答' 的检索步骤,page accuracy 可做辅助 reward。获取注意事项:SP 的 train 39,463 条在 lmms-lab-encoder/DocVQA 仓库里(parquet 存在但 README 中注释掉了,需用 data_files='DocVQA/…

核实备注:RRC portal license terms text not seen; 'VLMs saturated at ANLS 90+' claim not checked against a leaderboard; MP-DocVQA total: paper 46,176 vs HF card 46,436

2022 · WACV 2022, pp. 2582-2591, DOI 10.1109/W… · infographics downloaded from the Internet with th…

two-stage annotation by a small pool of annotators (not crowdsourced); questions over infographics requiring layout / text / graphic / data-visualization reasoning, with operation tags Counting, Arithmetic, Sorting and…

单图 infographic,视觉-文本-图表混排,题目带 Counting / Arithmetic / Sorting 的 operation 标注,比 DocVQA 难。不过 val/test 里约 70% 是 Image-span 单 span 抽取,大多数题一步就能答,planner 拆成证据链的空间有限,只有 Arithmetic / Counting / Sorting 和 Multi-span 这部分适合拆成 '定位区域 -> 读数 -> 计算'。它最强的用法是做 cost-aware routing:能拿 Textract OCR + 小 LM 的便宜路径对比大 VLM,难度梯度也明显。train 有 23,946 题,答案短,ANLS / EM 可以直接当 reward;它也是 VLM 评测的标配 benchmark,适合做二级 benchmark 或 sanity 集。缺点:test GT 不公开(RRC…

核实备注:RRC portal terms (download page requires login); row count of the 24 unregistered train parquet shards in the HF mirror

2024 · NeurIPS 2024 Datasets and Benchmarks Tr… · PDF documents of 7 types, rendered as page screen…

expert-annotated questions over long documents of 7 types (research reports, papers, guidebooks, brochures, tutorials, etc.), including single-page, cross-page and unanswerable

长文档(当前版本平均 47.5 页)多模态理解。约 1/3 的题跨页,约 22.5% 不可答。每题都标了 evidence_pages 和 evidence_sources(Chart/Table/Figure/Pure-text/Layout),正好对应我们按证据模态把子问题路由到不同模型(小 VLM / OCR+LLM / 大 VLM)的设定,也贴合 long-horizon 场景(先做页检索,再多轮调用)。官方 F1 会惩罚错误作答、鼓励正确 abstain,这和 cost budget 用完后 hard-to-answer 就停止的设计一致。适合当 out-of-domain 评测集。缺点:没有训练集,规模约 1.1k;数据是 CC BY-NC 4.0,只能用于研究;官方评测依赖 GPT-4o 抽取答案(有 API 成本)。另外要注意论文版(1,062)和当前版(1,091)的数字不同,报结果时要写明用的是哪个版本。

场景文字 / OCR VQA

2022 · NAACL 2025 (main, long; 2025.naacl-long… · RICO mobile app screenshots (images not in the Gi…

reading comprehension over mobile UI screenshots (includes unanswerable '<no answer>'); ComplexQA = counting / arithmetic / comparison across multiple screen regions

train/val/test 标签全部在 GitHub 公开,CC BY 4.0,8.6 万 QA,官方 metrics.py 直接给出 SQuAD 式 EM/F1,可以直接当 GRPO 的规则 reward,是少数“标签全公开且可 RL”的 text-rich 数据。不过原始 ScreenQA 的问题大多是单屏读取类,拆解空间小(decomposability 2);真正适合展示 planner 的是 ComplexQA(11,781 条,counting/arithmetic/comparison,答案由模型生成后人工验证),可以拆成 A/B 并行子问题再聚合,但它没有官方 split,需要按 image_id 自己切,并检查和 ScreenQA test 的图片重叠。router 视角:可以把 RICO view hierarchy 文本交给 text LLM、截图交给 VLM 或小 OCR 模型,再比较 cost,正好…

核实备注:whether ComplexQA images overlap the ScreenQA test split; HF mirror counts (68,980/8,618/8,427) differ slightly from GitHub

2019 · ICCV 2019 (DOI 10.1109/ICCV.2019.00470) · scene: Google-image-search photos of 500 business…

templated from KB facts with partial human paraphrase (560 distinct question strings in scene, 37 in movie). Three types: identify the entity by reading text, a one-hop KB attribute (director/author/year/country/CEO/gen…

适合作为 planner+router 的 easy/medium tier 和 cost-routing 的 testbed,但不适合作为主 benchmark。优点:问题天然是固定两跳 evidence chain(A: OCR/VLM 读出 brand/书名/片名 → B: 查 KB 拿属性 → 回答),而且有不少问题只需 A 步('Which movie is this?' 这类就是读 title,适合路由给小 OCR/VLM),yes/no 与 attribute 问题则需要 KB,因此 router 的 cost/accuracy trade-off 有信号。官方 KB-business/book/movie 可直接作 retrieval corpus;book+movie 有约 1.0M 条 train QA,单一 gold string,便于写 EM reward。风险:(1) 链条结构固定、浅(entity…

核实备注:no license stated; which of split codes 2/3 is val vs test; scene image tarball host unreachable from Beacon

TextVQAfit 3
2019 · CVPR 2019 · Open Images v3 (per the paper; the HF card says O…

natural questions that require reading and reasoning about scene text; 8.9% need combining multiple OCR tokens

text-rich VQA 的标准 baseline,几乎所有 VLM 都报。它有 3.46 万 train(2.2 万图),val 公开,标注是 CC BY 4.0,reward 现成可用。对我们主要有两个用处:一是作为『混合难度训练集』里的单跳 OCR 部分,二是证明 router 在简单题上能把任务交给小的 OCR/VLM 模型、省 cost 又不掉点。问题本身复杂度低,几乎不需要拆解或检索,不适合作为体现 planner 价值的主实验。test 只能走 EvalAI,评测用 val。数据加载建议直接用官方 JSON 加 images zip:HF 版本是 script loader,dataset viewer 不可用。

核实备注:textvqa.org license statement (JS-rendered page not readable); image licenses (Open Images / Flickr)

WebSRCfit 3
2021 · EMNLP 2021 (main conference, pp. 4173-4… · screenshot of a manually chosen segment of each w…

structural reading over a web page segment: key-value lookups, tables, and comparison questions (yes/no) across 3 domains of sites; answer is a text span on the page or yes/no

对 cost-aware router 有一个独特卖点:同一证据同时有 screenshot 和 HTML 两种模态,router 可以学会在『便宜的 text LLM 读 HTML / OCR 文本』和『贵的 VLM 看截图』之间做 trade-off,正好对应我们多粒度模型池的 cost 论点。train 30.7 万 QA 公开,CC BY 4.0(仅 HF card 写明),EM/F1 可直接作 GRPO reward。缺点:(1) 大多是单页单跳 span 抽取,只有 Comparison 类(6.9 万,yes/no)需要两次查找加一次比较,planner 分解空间有限;(2) 不需要外部检索;(3) test 标签不公开,需用 dev 当 test;(4) leaderboard 已接近饱和(SageGPT-small 89.11 EM / 92.15 F1,ScreenAI 5B 84.02 / 87.24),…

核实备注:formal POS metric definition not seen on the pages opened; CC BY 4.0 stated only on the HF card

OCR-VQAfit 2
2019 · ICDAR 2019 · Book covers from Iwana et al. book-cover genre da…

Template questions (title, author, genre, year, edition, binary genre 'Is this a X book?'), randomly replaced by human paraphrases; single-hop

体量大、train split 完整、测试标签公开、答案短,可作为 router 的『简单样本』/ warm-up 数据和 cost reward 的低端锚点:title/author/year 题用小 OCR 模型或小 VLM 就能答,genre 题(基线只有 22.0%)要从封面视觉 + 文本推断,可能值得调用更强的模型。但它模板化、单跳,基本不需要 planner decomposition,也不需要 retrieval,不适合作主 benchmark。另外 OCR-VQA train 常被放进开源 VLM 的 instruction-tuning 数据(例如 LLaVA 系列),池子里的 VLM 可能已经见过它,会夸大小模型的准确率,影响 cost/accuracy trade-off 的结论。license 未声明。HF 镜像是社区上传,不是作者官方版本。

核实备注:official Google Drive package contents/format not opened; no license stated (project page / HF card); exact matching rule for 'accuracy' not specified in the paper

2024 · v2: NeurIPS 2025 Datasets & Benchmarks… · aggregated from many existing OCR / scene-text /…

text recognition, referring/grounding, spotting, KIE, parsing (table/chart/document/formula), counting/calculation, understanding, reasoning VQA; EN and CN; leaderboard groups them into 8 EN and 5 CN capabilities

只适合当『OCR 能力体检 / OOD eval』用。v2 只有一个 10k 的 test split,没有 train split,题型以感知、识别、解析为主,不是 multi-hop QA,planner 很难拆出有意义的子问题链。可用之处有一个:每题都带 type(30 类,含 en/cn)和 dataset_name(112 个)细粒度标签,正好用来做 router 行为分析,比如看哪类子问题被派给小 OCR 模型、哪类给 VLM,以及 cost 和 accuracy 的分布,适合放进分析实验或附录。注意官方 vqa_evaluation 对短答案用的是子串包含,模型输出越长越容易得分。如果拿它当 cost-aware router 的 eval,要同时报告输出长度,或者另加一个 strict EM,否则长输出的大模型会占便宜。有 MIT license,答案公开,v2 进了 NeurIPS'25 D&B,v1 发在…

核实备注:absolute task count (paper body likely 23); whether the private 1.5k set's answers were released; licenses of aggregated upstream images

ST-VQAfit 2
2019 · ICCV 2019 (dataset paper, arXiv 1905.13… · 6 source groups: COCO-Text 7,520 img, Visual Geno…

scene-text reading questions over natural images (signs, brands, jerseys, plates); 3 tasks: Task 1 strongly contextualized (per-image 100-word dictionary), Task 2 weakly contextualized (30k global dictionary = 22k GT wo…

与 TextVQA 互补的经典 scene-text 集,ANLS (tau=0.5) 对 OCR 小错误宽容,适合做连续型 reward,也适合检验 router 能否把纯 OCR 子问题派给便宜的 OCR / 小 VLM 而非大模型。但它是单跳读字题,几乎不需要 planner 分解,也无检索需求;test 只能上 RRC 提交,license 未声明。train 带答案的数据可从 RRC 注册下载,也可用 HF 社区 mirror(vikhyatk/st-vqa、the_cauldron/st_vqa,非官方,计数与原文不完全一致)。建议只作为补充训练数据、低成本路由的 easy 样本或 OOD 评测。

核实备注:license not stated anywhere (RRC pages, paper, HF cards); paper-internal split inconsistency (1,018 images / 1,320 Q unassigned)

专家级推理(科学 / 数学)

M3CoTfit 3
2024 · ACL 2024 (Main, Long Papers), Anthology… · science: filtered ScienceQA images; mathematics:…

multi-step multimodal reasoning over science (natural/social/language science), mathematics (algebra, geometry, theory), commonsense (physical/social/temporal); built to require visual reasoning (image-free-answerable i…

设计目标是 multi-step + 必须看图(作者从 ScienceQA 里剔除了不看图就能答的样本),train 有 7,863 条,答案是字母,EM reward 现成,test 金标公开,可以直接作为 cost-aware GRPO 的训练/评测集;平均 10.9 步的 rationale 可以作为 planner 拆证据链的弱监督。三个 domain/9 个 topic 有利于 router 学领域路由,例如 math/geometry 交给 VLM + 推理模型,language-science 有时根本不需要视觉模型,正好用来检验 router 会不会省掉不必要的视觉模型调用。缺点:train 中 71% 是 ScienceQA 衍生的 science 题,难度偏低,mathematics 只有 812 条;论文里的多步主要指 CoT 步数,不是可以并行分派给不同模型的子问题;仍是多选、无检索语料、非 OCR/文…

核实备注:license: MIT only on HF YAML; GitHub repo has no LICENSE; HF test 2,318 vs paper 2,358 (40-item gap unexplained)

MMK12fit 3
2025 · arXiv preprint 2503.07365 (MM-Eureka, v… · Chinese K12 textbooks / exam papers (diagrams, ta…

K12 multimodal reasoning: train = math fill-in-the-blank; test = 4-subject science MCQ (mostly secondary level); human-verified answers; the CoT solutions described in the paper are not in the released HF columns

它的价值在于 RL 训练池,而不是复杂 QA benchmark:15,616 道 train 题,答案是 Math-Verify 可规则校验的短答案(fill-in-the-blank),正好补上 MMMU、MathVista、MATH-Vision、EMMA 这类评测集没有 train split 的缺口,可以直接当 router GRPO 的 math 训练池,cost-aware reward 也能直接复用 Math-Verify。注意 train 与 test 格式不一致:train 只有 math 填空,test 是 2,000 道 4 学科 MCQ(各 500),train 训出来、test 上评测存在格式/学科迁移。缺点:单图单题,不需要检索,planner 分解价值一般;HF 上没有 CoT solution 列;数据 license 未标注,使用前需要确认。

核实备注:dataset license (none on HF card; GitHub code Apache-2.0 does not cover data); no peer-reviewed venue found

MMMUfit 3
2023 · CVPR 2024 (Oral) · college exams, quizzes and textbooks; 30 image ty…

college-level expert questions over 6 disciplines / 30 subjects / 183 subfields; interleaved image-text, some multi-image, some with images in options; topic_difficulty Easy/Medium/Hard (28/45/27%)

适合作为 OOD 评测集而不是训练集。问题是 knowledge-intensive + perception 混合(先读图中表格 / 化学结构 / 乐谱,再调用学科知识),天然可拆成『视觉感知子问题→文本知识推理子问题』,给 router 一个区分『该用小视觉模型 / VLM / 纯文本 LLM』的场景;MMStar (2403.20330) 指出部分 MMMU 题不看图也能答,正好可用来检验 router 是否学会『不调用视觉模型』以省 cost。缺点:没有 train split(dev 150 + validation 900),没有检索语料,94% 是多选题,cost-aware reward 的正确率信号偏粗(选项数不固定,随机基线未核实)。test 10.5K 标签已于 2026-02-12 公开,可本地评测;但用它训练会污染评测。可考虑同时用更难的 MMMU-Pro。

核实备注:random-choice baseline (options are not always 4; paper rows not read)

2024 · ACL 2025 (Long Papers), aclanthology 20… · MMMU validation+test questions, filtered by 4 tex…

college-level expert multi-discipline questions (art, business, science, medicine, humanities, engineering). Text-only-answerable items are removed and options are expanded to 10. In the vision setting, no separate text…

适合当 router 的 OOD 评测集,不适合当主训练集。text-only 可答的题已用 4 个 open LLM 过滤掉,所以『不看图直接用小 LLM 答』这条 shortcut 基本被堵死。vision 子集把题干和选项都渲染进截图,正好可以对比两条链路:小 OCR / 小 VLM 先抽文字再交给文本 LLM 推理(低 cost),还是直接调大 VLM(高 cost),能清楚看到 cost-accuracy trade-off。论文结论 'OCR prompts have minimal effect, CoT generally helps' 也能当 baseline 参照。局限:(1) 只有 test 1,730 题,没有 train split,GRPO 训练得换别的数据集,或者自己切分(会影响和 leaderboard 的可比性);(2) 每题基本是单题专家推理(感知→推理),可分解成证据链的成分有限,plan…

核实备注:exact answer-extraction parser (paper only says prompts end with 'Answer: $LETTER'); whether every 10-option row has exactly 10 options (full parquet not downloaded)

2022 · NeurIPS 2022 · science-curriculum questions (the paper describes…

grade 1-12 science multiple-choice questions; image and/or text (hint) context; lectures annotated for 83.9% and solutions (explanations) for 90.5%

本类里少数有完整 train/val/test 且 test 有标签的数据集。51.3%(10,876/21,208)题目不含图像,其中 7,188 题连 hint 文本上下文都没有——正好用来训练 router 学会『这题不需要视觉模型,用便宜的文本模型就行』的省 cost 行为(对应头脑风暴里『有些问题不需要图像模型』)。按 TXT/IMG/NO 拆分的官方指标可以直接对照『按模态路由』的效果。lecture 字段(256 个不同 lecture)可以做 planner knowledge 库的原型。缺点:难度低(小学到高中),leaderboard 最高已到 96.18(fine-tuned),大多数题一步就能答完,几乎拆不出证据链;适合拿来把 pipeline 跑通、做 sanity check 和 cost 行为分析,不适合当主实验。注意数据 license 是 CC BY-NC-SA 4.0。

核实备注:that the 2,017-Q IMG test subset equals the 'ScienceQA-IMG' set reported by LLaVA-style papers (from memory, not re-opened)

EMMAfit 2
2025 · ICML 2025 (Oral; first announced as Spo… · Math: re-filtered from MathVista/MathVision/RAVEN…

organic multimodal reasoning: items built so they cannot be solved by reasoning about each modality separately (math spatial/pattern, physics diagrams, chemistry structures/reactions, code<->visualization matching)

EMMA 是专门构造成『不能把图像和文本分开解决』的,正好用来压力测试 planner:如果把问题拆成相互独立的视觉子问题和文本子问题,在这里会被惩罚,所以适合做 failure-mode 分析或负面对照(例如对比 decompose vs. 直接调用强 VLM 的 accuracy / cost)。gold 可以规则判分(字母 EM + latex2sympy),但只有 test(2788,mini 400),license 未声明,Math/Physics 大半来自 MathVista/MathVision 等已有 benchmark,有泄漏风险。题目偏 STEM 推理,不需要 retrieval / OCR,和多模态 RAG + router 的主线不太对口。不适合主训练,可以作为 out-of-domain 的 held-out eval(建议用 EMMA-mini 控制 API cost)。

核实备注:no license on HF card or GitHub; card's 1,796 'newly constructed' vs 1,678 new_annotated in the source statistics

2024 · NeurIPS 2024 Datasets and Benchmarks Tr… · real math competitions: 19 competitions — Math Ka…

competition math with visual context (diagrams, figures); 16 subjects incl. Algebra, Analytic/Combinatorial/Descriptive/Solid/Transformation Geometry, Metric Geometry (Angle/Area/Length), Arithmetic, Counting, Combinato…

难度高,每题带 5 级 difficulty 标签和 16 类 subject 标签,适合分析 router 是否随难度升级模型(按 level 画 cost vs accuracy 分层曲线),可以当 eval-only 的 OOD 测试集。但它是竞赛数学,瓶颈在单个强模型的深度推理,不在证据拆解或检索;异构小视觉模型池帮助有限,planner + router 的优势难体现。没有 train split,RL 训练只能借用别的数据。

核实备注:how testmini (304) was sampled; answer-extraction rule (paper does not specify; VLMEvalKit uses LLM extraction)

2023 · ICLR 2024 (Oral) · 28 existing math-related datasets (PlotQA, ChartQ…

math reasoning in visual contexts: charts/plots, tables, geometry diagrams, function plots, IQ puzzles, scientific/textbook figures, academic paper figures, natural images with counting/arithmetic

内容上和我们的 model pool 很契合:chart/table/OCR 类的子问题可以交给小视觉模型或 OCR,数值推理交给文本 LLM,geometry 交给强 VLM,适合展示 router 按子问题分配模型、省 cost。free_form numeric 答案配上 precision 字段,可以做比多选更细的 rule-based 判分。但这个数据集没有 train split,README 也明确禁止拿它当训练集,test 标签又不公开,所以只能当 held-out eval(testmini 1k 本地打分)。训练数据得从它的源数据集取,例如 ChartQA、DVQA、PlotQA、TabMWP、Geometry3K、GeoQA+ 的 train split(各自的 license 需要单独核对)。题目多为单跳视觉数学,需要多步证据链的题比例有限,对 planner 拆题能力的考验一般。

通用与组合式基线

2019 · CVPR 2019 (oral) · Visual Genome natural images (COCO / Flickr)

Compositional questions generated by a question engine from scene graphs: relations, attributes, comparisons, logical and/or, multi-step spatial reasoning. The answer distribution is balanced per question group.

In this family GQA is the strongest set for sanity checks and for producing training signal. Each question in train/val/testdev carries a gold functional program in the 'semantic' field (for example select -> relate -> filter -> query, with dependencies). That program can serve as gold or silver supervision for the planner's evidence chain and as a checker for decompositions. It also comes with 'entailed'/'equivalen…

核实备注:total image count (~113K commonly cited, not on official pages); whether the EvalAI GQA challenge still accepts submissions; '60%+ on testdev' claim for open VLMs not re-verified

MMStarfit 3
2024 · NeurIPS 2024 (Advances in NeurIPS 37, p… · Images re-selected from MMBench and SEED-Bench (n…

Human-reviewed, vision-indispensable MC questions over 18 axes. CP: style/quality, scene/topic, emotion. FP: attribute & celebrity recognition, object location, counting. IR: single-instance attribute, cross-instance co…

MMStar 的设计目标就是剔除 text-only LLM 能答对的题(vision-indispensable),而且论文给出了 S_v、S_wv、S_t 三种设置和 MG/ML 公式,可以直接复用来量化 router 跳过视觉模型的代价:用 router 版本对比 always-VLM 和 text-only 两个版本的 accuracy 与 cost。在 MMStar 上,'不调视觉模型' 理应明显掉分,可以作为 router 学会该调 VLM 时就调的 sanity check。相比之下 MMBench/SEED 的 leakage 高,router 偷懒也不容易被罚。它的局限有三点:只有 1.5k 条;只有 val,没有 train split;题目是单图单步 MC,multi-hop 分解空间小,planner 发挥余地有限。另外 license 未声明,数据来自 6 个上游 benchmark。定位是 held…

核实备注:no license declared (HF card / GitHub); per-source sample counts (only in paper Fig. 4)

2017 · CVPR 2017 · Synthetic Blender renders of 3D primitives

Template-generated multi-step compositional questions (count, compare, exist, query attribute, chains of spatial relations)

Fully controlled compositional reasoning with gold programs. Useful as a unit test that the planner produces correct sub-question chains, and that the router learns when a cheap detector/counter suffices versus a VLM. CoGenT provides a free compositional-generalization split. But it is synthetic, has no OCR, knowledge or retrieval, and neuro-symbolic models have largely solved it. Reviewers will treat it as a toy sa…

核实备注:Super-CLEVR license (not named in README); closed answer vocabulary size not checked

MMBenchfit 2
2024 · ECCV 2024 (Oral); arXiv 2307.06281 firs… · >80% Internet-sourced (2,590 items, 80.5%); the r…

Single-image multiple-choice questions (with optional hint) over 20 leaf ability dimensions in 3 levels: L-1 Perception / Reasoning; L-2 Coarse Perception, Fine-grained Single-instance, Fine-grained Cross-instance, Attr…

适合作为 VLM-agent 表格里的 general-ability sanity row(建议用 Dev EN 1,164,可本地打分)。20 个 ability dimension 的 taxonomy 可以用来分析 router 对不同 ability 选了 pool 里哪个模型。缺点:MC、大多单步、没有 train split、Test 标签隐藏,不考验 evidence decomposition、OCR-heavy evidence 或 retrieval。论文称用 LLM + 人工过滤过 text-only 可答题,但没给数量;MMStar 关于 text-only solvability / leakage 的批评本轮未复核。

核实备注:MMBench v1.1 sizes; paper 3,217 vs README 2,974 vs 1,164+1,784=2,948 item counts disagree; MMStar's text-only-solvability critique not re-verified

2023 · SEED-Bench-1:arXiv 技术报告 2307.16125(2023… · 图片:CC3M(caption 用 Tag2Text 重新生成)。视频:Something-Som…

ChatGPT/GPT-4 根据视觉信息生成题干和 4 个选项,三个 text-only LLM 都能答对的题被过滤掉,再由人工核对答案、归维度。共 12 维:9 个 spatial(scene、instance identity / attributes / location / counting、spatial relation、interaction、visual reasoning、text understanding),3…

规模大、标签公开,适合便宜地做大范围回归检查。分维度 accuracy 能看出 router 有没有把 counting(2,447 题)、text understanding(85 题)这类题派给专用的小模型,这是 cost-aware routing 的一个诊断角度。题目基本是单步的,训练不了 planner 的证据链分解,也用不上 retrieval。SEED-Bench-2-Plus(2,277 题 chart / map / web,text-rich)最贴近我们的 document / chart 方向,可以和 ChartQA 一起细看,但同样只有 test。MMStar 测过 SEED-Image:text-only LLM 2-shot 26.8–40.7%(随机 25%),存在不看图也能答的题,但程度中等。注意数据是 CC-BY-NC-4.0,只能做研究用途。

核实备注:exact sizes of SEED-Bench-2 (~24K) and SEED-Bench-H (~28K), README approximations only

VQA v2fit 2
2017 · CVPR 2017 (DOI 10.1109/CVPR.2017.670);… · COCO natural images (train2014 / val2014 / test20…

Open-ended crowd-sourced questions, mostly single-step perception (yes/no, number, other). They are balanced by complementary image pairs to reduce language priors.

The canonical sanity baseline. For us its value is as the 'easy' end of the cost curve. Most questions are single-step perception and need no decomposition, so they should be routed to the smallest vision model. That tests whether the cost penalty makes the router avoid over-calling large models. It is too easy and single-hop to show the planner's value. It is saturated by modern VLMs (above 80%), and test labels ar…

核实备注:exact test-dev size (107,394 commonly cited; official pages give no count); image license (visualqa.org/terms.html states none)

2020 · CVPR 2020 (oral) · COCO train2014/val2014 (via VQA v2)

VQA v2 reasoning question (e.g. 'is this a double decker bus?') with crowd-written perception sub-QA from about 3 workers, each giving 1 to n flat sub-questions with short answers

这是唯一带人工 gold 分解的自然图像 VQA 数据(每个 Reasoning question 平均约 3.1 条 perception sub-QA),可以作为 evidence planner 的辅助监督,或者用来做 consistency probe(检查 main 答对时 sub 是否也答对)。局限有四点。第一,分解是扁平、冗余的 per-worker 列表,没有依赖边,也没有多跳链,教不了证据图结构。第二,约 77-89% 是 yes/no 题,没有 OCR、retrieval 或 knowledge pool,router 几乎总会选小型 VQA 模型,cost-aware routing 学不到有区分度的信号。第三,sub_answer 是单人标注,有噪声。第四,没有 test split,需要自己从 train 里切 dev,val 作 test。适合做 planner 预训练或辅助 reward,不适合做…

核实备注:why JSON main-question key counts exceed the paper's counts (train +720, val +1,116)

2018 · CVPR 2018 (DOI 10.1109/CVPR.2018.00380)… · Phone photos taken by blind / low-vision users (o…

Spoken, conversational real-user questions; often reading text (labels, screens) or identifying objects; about 27% unanswerable; occasionally compound (e.g. 'What is this? And what color is it?')

Useful for one design element: the user's rule 'if still hard to answer when cost hits the budget, stop'. The answerable label and the 'unanswerable' gold answer (27% of train) give a gold signal for abstention under a budget. The set also mixes OCR-needed and OCR-free questions, which rewards a router that calls an OCR or text-rich VLM only when needed. Against that, questions are short and single-hop, with no evid…

核实备注:whether the lmms-lab HF test split carries answers (viewer broken)